AI Model Tracker
Recent model launches with their API prices and the benchmark results published by each lab, linked back to the official announcement.
Latest releases
Anthropic · launched 9 Nov 2026
Released alongside the access-limited Claude Mythos 5.2. Tokens cost 20% less than Fable 5.1, with output generated up to 30% faster and an optional fast mode at $16 input and $80 output.
- Input / 1M
- $8.00
- Output / 1M
- $40
- Context
- 1M
OpenAI · launched 26 Oct 2026
A fast, efficient model for computer use, visual reasoning and writing, priced 50% below GPT-6.1 Sol.
- Input / 1M
- $1.00
- Output / 1M
- $5.00
- Context
- 1.05M
Listed rates apply up to 272K input tokens. Above 272K, input costs $2, cached input $0.10 and output $7.50 per million tokens for the full request.
Anthropic · launched 7 Oct 2026
Anthropic's fastest small model for high-volume tasks, live support and subagents, with adaptive thinking and adjustable effort.
- Input / 1M
- $0.10
- Output / 1M
- $0.50
- Context
- 1M
Listed prices and comparisons apply to prompts up to 100K tokens. Above 100K, input costs $0.50, output $2.50 and cache reads $0.05 per million tokens.
Google DeepMind · launched 30 Sept 2026
Google's newest frontier model for long-running coding, knowledge work and cybersecurity defense, generally available in the Gemini API and app since 13 October 2026.
- Input / 1M
- $2.00
- Output / 1M
- $10
- Context
- 1.05M
Introductory rates through 30 November 2026. From 1 December 2026, input is $4, output $20 and cached input $0.20 per million tokens. Caching is implicit only. Long decode raises the output limit to 1,048,576 tokens.
OpenAI · launched 29 Sept 2026
An upgrade to GPT-6 Sol for coding, professional work and computer use, with cached input priced 50% lower.
- Input / 1M
- $2.00
- Output / 1M
- $10
- Context
- 1.05M
Listed rates apply up to 272K input tokens. Above 272K, input costs $4, cached input $0.20 and output $15 per million tokens for the full request.
Anthropic · launched 28 Sept 2026
The second model in the Claude 5.5 family. Input and output prices match Sonnet 5, it runs more than 30% faster and needs fewer tokens per task.
- Input / 1M
- $2.00
- Output / 1M
- $10
- Context
- 1M
Cache reads were reduced from $0.20 to $0.10 per million tokens on 7 October 2026.
Anthropic · launched 22 Sept 2026
Anthropic's newest Opus model. Tokens cost 20% less than Opus 5 and cache reads 60% less, with output generated more than 30% faster.
- Input / 1M
- $4.00
- Output / 1M
- $20
- Context
- 1M
OpenAI · launched 22 Sept 2026
The lowest-cost model in the GPT-6 family, positioned below GPT-6 Sol and the flagship GPT-6 Astra.
- Input / 1M
- $0.10
- Output / 1M
- $0.50
- Context
- 1.05M
SpaceXAI · launched 21 Sept 2026
Grok's latest main model for coding, agentic tasks and professional knowledge work, with adjustable reasoning effort.
- Input / 1M
- $2.00
- Output / 1M
- $6.00
- Context
- 500K
Base rates apply up to 200K context tokens; higher-context requests use different rates. Batch API is not supported. The separate fast variant costs twice as much.
OpenAI · launched 4 Sept 2026
OpenAI's flagship GPT-6 model, positioned above GPT-6 Sol and Luna for the most demanding professional work, coding and computer use.
- Input / 1M
- $10
- Output / 1M
- $50
- Context
- 1.05M
Google DeepMind · launched 2 Sept 2026
Google's latest stable Flash model for long-horizon software engineering, autonomous agents and complex enterprise workflows.
- Input / 1M
- $0.75
- Output / 1M
- $3.75
- Context
- 1.05M
Introductory rates through 31 December 2026. From 1 January 2027, input is $1.50, output $7.50 and cached input $0.15 per million tokens. Cache storage and grounding are billed separately.
Google DeepMind · launched 21 Jul 2026
Google's fastest, most economical 3.5-class model for high-volume agentic tasks, translation and simple data processing.
- Input / 1M
- $0.30
- Output / 1M
- $2.50
- Context
- 1.05M
Text, image, video and audio inputs share the listed rate. Cache storage and grounding are billed separately.
Google DeepMind · launched 19 Feb 2026
Preview
Google's publicly available Pro model for complex reasoning, multimodal understanding and agentic coding, currently in preview.
- Input / 1M
- $2.00
- Output / 1M
- $12
- Context
- 1.05M
Rates apply to prompts up to 200K tokens. Above 200K, input is $4, output $18 and cached input $0.40 per million tokens. Cache storage and grounding are billed separately.
API pricing
| Model | Launched | Input / 1M | Output / 1M | Cached / 1M | Blended / 1M |
|---|---|---|---|---|---|
| Claude Fable 5.2Anthropic | 9 Nov 2026 | $8.00 | $40 | $0.20 | $16 |
| GPT-6.1 TerraOpenAIListed rates apply up to 272K input tokens. Above 272K, input costs $2, cached input $0.10 and output $7.50 per million tokens for the full request. | 26 Oct 2026 | $1.00 | $5.00 | $0.05 | $2.00 |
| Claude Haiku 5.5AnthropicListed prices and comparisons apply to prompts up to 100K tokens. Above 100K, input costs $0.50, output $2.50 and cache reads $0.05 per million tokens. | 7 Oct 2026 | $0.10 | $0.50 | $0.01 | $0.20 |
| Gemini 4 ArgonGoogle DeepMindIntroductory rates through 30 November 2026. From 1 December 2026, input is $4, output $20 and cached input $0.20 per million tokens. Caching is implicit only. Long decode raises the output limit to 1,048,576 tokens. | 30 Sept 2026 | $2.00 | $10 | $0.10 | $4.00 |
| GPT-6.1 SolOpenAIListed rates apply up to 272K input tokens. Above 272K, input costs $4, cached input $0.20 and output $15 per million tokens for the full request. | 29 Sept 2026 | $2.00 | $10 | $0.10 | $4.00 |
| Claude Sonnet 5.5AnthropicCache reads were reduced from $0.20 to $0.10 per million tokens on 7 October 2026. | 28 Sept 2026 | $2.00 | $10 | $0.10 | $4.00 |
| Claude Opus 5.5Anthropic | 22 Sept 2026 | $4.00 | $20 | $0.20 | $8.00 |
| GPT-6 LunaOpenAI | 22 Sept 2026 | $0.10 | $0.50 | $0.01 | $0.20 |
| GPT-6 SolOpenAIListed rates apply up to 272K input tokens. Above 272K, input costs $4, cached input $0.40 and output $15 per million tokens for the full request. | 22 Sept 2026 | $2.00 | $10 | $0.20 | $4.00 |
| Grok 4.7SpaceXAIBase rates apply up to 200K context tokens; higher-context requests use different rates. Batch API is not supported. The separate fast variant costs twice as much. | 21 Sept 2026 | $2.00 | $6.00 | $0.50 | $3.00 |
| GPT-6 AstraOpenAI | 4 Sept 2026 | $10 | $50 | $1.00 | $20 |
| Gemini 3.8 FlashGoogle DeepMindIntroductory rates through 31 December 2026. From 1 January 2027, input is $1.50, output $7.50 and cached input $0.15 per million tokens. Cache storage and grounding are billed separately. | 2 Sept 2026 | $0.75 | $3.75 | $0.075 | $1.50 |
| Claude Fable 5.1Anthropic | 1 Sept 2026 | $10 | $50 | $0.25 | $20 |
| Claude Opus 5Anthropic | 24 Jul 2026 | $5.00 | $25 | $0.50 | $10 |
| Gemini 3.5 Flash-LiteGoogle DeepMindText, image, video and audio inputs share the listed rate. Cache storage and grounding are billed separately. | 21 Jul 2026 | $0.30 | $2.50 | $0.03 | $0.85 |
| GPT-5.6 LunaOpenAI | 9 Jul 2026 | $0.20 | $1.20 | $0.02 | $0.45 |
| GPT-5.6 SolOpenAIPrice before the GPT-6 launch, from OpenAI's announcement. OpenRouter now lists $2 / $10. | 9 Jul 2026 | $4.00 | $20 | – | $8.00 |
| GPT-5.6 TerraOpenAIOpenAI's model documentation supports the Batch API but does not list a batch price. | 9 Jul 2026 | $2.00 | $12 | $0.20 | $4.50 |
| Claude Sonnet 5Anthropic | 30 Jun 2026 | $2.00 | $10 | $0.20 | $4.00 |
| Claude Fable 5Anthropic | 9 Jun 2026 | $10 | $50 | $1.00 | $20 |
| Gemini 3.1 ProGoogle DeepMind · PreviewRates apply to prompts up to 200K tokens. Above 200K, input is $4, output $18 and cached input $0.40 per million tokens. Cache storage and grounding are billed separately. | 19 Feb 2026 | $2.00 | $12 | $0.20 | $4.50 |
| Claude Haiku 4.5Anthropic | 15 Oct 2025 | $1.00 | $5.00 | $0.10 | $2.00 |
Standard API prices in USD per million tokens, checked 2 Oct 2026 via OpenRouter. Blended assumes 3 input tokens for every output token. Batch discounts vary by model. Google and Grok prices were rechecked on 27 October 2026 against their official sources, linked in each model's details. Argon rates are introductory prices through 30 November 2026. Haiku 5.5 and Sonnet 5.5 prices were updated from Anthropic's 7 October 2026 announcement. GPT-6.1 Sol and GPT-6 Sol prices were checked on 8 October 2026 against OpenAI's announcement and model documentation. GPT-6.1 Terra prices were checked on 27 October 2026 against OpenAI's announcement and model documentation. Claude Fable 5.2 prices are from Anthropic's 9 November 2026 announcement.
Official benchmark results
Anthropic: Introducing Claude Fable 5.2 and Claude Mythos 5.2Read announcement
Reported by Anthropic on 9 Nov 2026 · exact values
| Benchmark | Claude Fable 5.2 | Claude Fable 5.1 | Claude Opus 5.5 | GPT-6 Astra |
|---|---|---|---|---|
| FrontierCode 2.0Agentic coding | 49.1% | 32.4% | 45.5% | 42.8% |
| FrontierSWE v2Agentic coding | 69.9% | 56.3% | 62.3% | 65.5% |
| AutomationBenchBusiness workflows | 51.4% | 31.4% | 42.5% | 41.4% |
| Terminal-Bench-Science 0.1Agentic scientific research | 74.6% | 52.6% | 58.7% | 68.1% |
| WANDRAgentic search · relaxed score | 82.1% | 68.7% | 72.3% | – |
| OSWorld 2.1Computer use · offline set, partial | 89.3% | 83.5% | 87.2% | 79.5% |
| RoboDojo SimRobotics | 64.9% | 27.6% | 39.4% | 29.8% |
| AA-Briefcase v1.1Knowledge work · rubric | 66.1% | 61.5% | 61.2% | 52% |
| AA-Briefcase v1.1 (Elo)Knowledge work | 1785 Elo | 1669 Elo | 1800 Elo | 1569 Elo |
| Remote Labor IndexKnowledge work | 41.3% | 17.9% | 21.3% | 20.8% |
| Humanity's Last ExamMultidisciplinary reasoning · with tools | 74.2% | 65.6% | 67.7% | 57.2% |
| ChartographyVisual chart recognition · no tools | 73.4% | 44.8% | 64.4% | 71% |
- Bold marks the best reported score in each row.
- Scores for the Claude models are with production safeguards on and at each model's highest effort, except FrontierCode 2.0 (Fable 5.2 and 5.1 at xhigh) and Remote Labor Index (Fable 5.2 at high).
- Claude Mythos 5.2, the same underlying model with access limited to vetted organizations, scores 75.3% on Terminal-Bench-Science 0.1. The cybersecurity and protein design rows report Mythos scores, so they are not shown here.
- Anthropic's table also includes Gemini 4 Carbon, which has no published API price, so it is not tracked here. RoboDojo Sim scores were run internally by Anthropic.
- A dash means the lab did not report a result for that model.
Accuracy against cost · reported by Anthropic on 9 Nov 2026 · exact values
Whether a model's code changes would be merged by the maintainers of open-source repositories.
- Claude Fable 5.2
- Claude Opus 5.5
- Claude Fable 5.1
- GPT-6 Astra
Show data table
| Model | Effort | Score | Cost per task |
|---|---|---|---|
| Claude Fable 5.2 | low | 34.2% | $2.10 |
| Claude Fable 5.2 | medium | 37.6% | $2.48 |
| Claude Fable 5.2 | high | 45.3% | $6.72 |
| Claude Fable 5.2 | xhigh | 49.1% | $14.2 |
| Claude Fable 5.2 | max | 45.6% | $44.7 |
| Claude Opus 5.5 | low | 14.7% | $0.75 |
| Claude Opus 5.5 | medium | 30.1% | $1.70 |
| Claude Opus 5.5 | high | 34.5% | $2.42 |
| Claude Opus 5.5 | xhigh | 43.4% | $5.18 |
| Claude Opus 5.5 | max | 45.5% | $12.8 |
| Claude Fable 5.1 | low | 20.6% | $3.01 |
| Claude Fable 5.1 | medium | 21.5% | $3.89 |
| Claude Fable 5.1 | high | 25.7% | $5.39 |
| Claude Fable 5.1 | xhigh | 32.4% | $8.68 |
| Claude Fable 5.1 | max | 31.7% | $11.5 |
| GPT-6 Astra | low | 31.1% | $2.44 |
| GPT-6 Astra | medium | 36.8% | $3.49 |
| GPT-6 Astra | high | 38.3% | $4.28 |
| GPT-6 Astra | xhigh | 41.4% | $4.54 |
| GPT-6 Astra | max | 42.8% | $6.68 |
- Exact score and cost values from the chart data published with Anthropic's announcement.
- Anthropic's chart also shows Gemini 4 Carbon, which has no published API price, so it is not tracked here.
Accuracy against cost · reported by Anthropic on 9 Nov 2026 · exact values
Perplexity's benchmark of agents on large data-collection tasks.
- Claude Fable 5.2
- Claude Opus 5.5
- Claude Fable 5.1
Show data table
| Model | Effort | Score | Cost per attempt |
|---|---|---|---|
| Claude Fable 5.2 | low | 71.4% | $12.7 |
| Claude Fable 5.2 | medium | 73.6% | $15.7 |
| Claude Fable 5.2 | high | 79.3% | $29.2 |
| Claude Fable 5.2 | xhigh | 80.6% | $39.8 |
| Claude Fable 5.2 | max | 82.1% | $53.1 |
| Claude Opus 5.5 | low | 31.2% | $1.25 |
| Claude Opus 5.5 | medium | 62.8% | $11.4 |
| Claude Opus 5.5 | high | 67.3% | $17.3 |
| Claude Opus 5.5 | xhigh | 71.3% | $29.3 |
| Claude Opus 5.5 | max | 72.3% | $38.7 |
| Claude Fable 5.1 | low | 63.3% | $24.4 |
| Claude Fable 5.1 | medium | 64.5% | $28.8 |
| Claude Fable 5.1 | high | 66.7% | $37.6 |
| Claude Fable 5.1 | xhigh | 67.7% | $44.5 |
| Claude Fable 5.1 | max | 68.7% | $51.1 |
- Exact score and cost values from the chart data published with Anthropic's announcement.
Pass rate against cost · reported by Anthropic on 9 Nov 2026 · exact values
Expert-level questions across many disciplines, answered with access to tools.
- Claude Fable 5.2
- Claude Opus 5.5
- Claude Fable 5.1
Show data table
| Model | Effort | Pass rate | Cost per attempt |
|---|---|---|---|
| Claude Fable 5.2 | low | 68.4% | $0.19 |
| Claude Fable 5.2 | medium | 68.6% | $0.21 |
| Claude Fable 5.2 | high | 71.5% | $0.63 |
| Claude Fable 5.2 | xhigh | 73.4% | $1.48 |
| Claude Fable 5.2 | max | 74.2% | $4.51 |
| Claude Opus 5.5 | low | 57.4% | $0.08 |
| Claude Opus 5.5 | medium | 63% | $0.17 |
| Claude Opus 5.5 | high | 63.9% | $0.29 |
| Claude Opus 5.5 | xhigh | 66.4% | $0.69 |
| Claude Opus 5.5 | max | 67.7% | $2.18 |
| Claude Fable 5.1 | low | 60.2% | $0.59 |
| Claude Fable 5.1 | medium | 62.4% | $0.85 |
| Claude Fable 5.1 | high | 63.1% | $1.37 |
| Claude Fable 5.1 | xhigh | 65.2% | $2.70 |
| Claude Fable 5.1 | max | 65.6% | $3.77 |
- Exact score and cost values from the chart data published with Anthropic's announcement.
- GPT-6 Astra scores 57.2% at max effort; Anthropic reports no cost for it.
Accuracy against cost · reported by Anthropic on 9 Nov 2026 · exact values
How accurately a model reads charts and figures.
- Claude Fable 5.2
- Claude Opus 5.5
- Claude Fable 5.1
Show data table
| Model | Effort | Score | Cost per attempt |
|---|---|---|---|
| Claude Fable 5.2 | low | 64.2% | $0.03 |
| Claude Fable 5.2 | medium | 66.4% | $0.03 |
| Claude Fable 5.2 | high | 69.8% | $0.07 |
| Claude Fable 5.2 | xhigh | 71.4% | $0.15 |
| Claude Fable 5.2 | max | 73.4% | $0.75 |
| Claude Opus 5.5 | low | 57% | $0.02 |
| Claude Opus 5.5 | medium | 59% | $0.03 |
| Claude Opus 5.5 | high | 59.2% | $0.03 |
| Claude Opus 5.5 | xhigh | 62.4% | $0.08 |
| Claude Opus 5.5 | max | 64.4% | $0.49 |
| Claude Fable 5.1 | low | 36.6% | $0.03 |
| Claude Fable 5.1 | medium | 42.2% | $0.05 |
| Claude Fable 5.1 | high | 46% | $0.08 |
| Claude Fable 5.1 | xhigh | 47% | $0.38 |
| Claude Fable 5.1 | max | 44.8% | $0.87 |
- Exact score and cost values from the chart data published with Anthropic's announcement.
- GPT-6 Astra scores 71.0% at max effort and Gemini 4 Carbon 72.5%; Anthropic reports no cost for either.
OpenAI: Introducing GPT-6.1 TerraRead announcement
Score against cost · reported by OpenAI on 26 Oct 2026 · exact values
Professional computer-use tasks, such as turning architectural drawings into a 3D model or logging an animated film shot by shot.
- GPT-6.1 Terra
- GPT-5.6 Terra
- GPT-6.1 Sol
- GPT-6 Astra
- GPT-6 Luna
- Claude Opus 5.5
Show data table
| Model | Effort | Score (%) | Cost per task |
|---|---|---|---|
| GPT-6.1 Terra | low | 55.9% | $0.16 |
| GPT-6.1 Terra | medium | 57.6% | $0.29 |
| GPT-6.1 Terra | high | 57.2% | $0.39 |
| GPT-6.1 Terra | xhigh | 58.5% | $0.66 |
| GPT-6.1 Terra | max | 60% | $1.01 |
| GPT-5.6 Terra | low | 40.2% | $0.59 |
| GPT-5.6 Terra | medium | 42.6% | $0.84 |
| GPT-5.6 Terra | high | 46.6% | $1.72 |
| GPT-5.6 Terra | xhigh | 48.5% | $2.50 |
| GPT-5.6 Terra | max | 50.7% | $3.58 |
| GPT-6.1 Sol | low | 52.4% | $0.70 |
| GPT-6.1 Sol | medium | 53.8% | $1.31 |
| GPT-6.1 Sol | high | 55.3% | $1.45 |
| GPT-6.1 Sol | xhigh | 56.5% | $1.45 |
| GPT-6.1 Sol | max | 58.6% | $2.00 |
| GPT-6 Astra | low | 53.4% | $3.55 |
| GPT-6 Astra | medium | 57.6% | $4.82 |
| GPT-6 Astra | high | 57.8% | $5.15 |
| GPT-6 Astra | xhigh | 58.3% | $5.91 |
| GPT-6 Astra | max | 59.3% | $7.24 |
| GPT-6 Luna | low | 36.3% | $0.022 |
| GPT-6 Luna | medium | 46.8% | $0.093 |
| GPT-6 Luna | high | 43.6% | $0.087 |
| GPT-6 Luna | xhigh | 47.9% | $0.093 |
| GPT-6 Luna | max | 50.9% | $0.14 |
| Claude Opus 5.5 | max | 63.2% | $8.82 |
- Exact score and cost values from the chart data embedded in OpenAI's announcement.
Score against cost · reported by OpenAI on 26 Oct 2026 · exact values
Visual reasoning across expert-level, multi-discipline questions.
- GPT-6.1 Terra
- GPT-5.6 Terra
- GPT-6.1 Sol
- GPT-6 Astra
- GPT-6 Luna
Show data table
| Model | Effort | Score (%) | Cost per task |
|---|---|---|---|
| GPT-6.1 Terra | low | 83.7% | $0.0038 |
| GPT-6.1 Terra | medium | 84.6% | $0.0041 |
| GPT-6.1 Terra | high | 85% | $0.0045 |
| GPT-6.1 Terra | xhigh | 85.4% | $0.0055 |
| GPT-6.1 Terra | max | 85.5% | $0.012 |
| GPT-5.6 Terra | low | 74.9% | $0.011 |
| GPT-5.6 Terra | medium | 76.4% | $0.012 |
| GPT-5.6 Terra | high | 77.5% | $0.014 |
| GPT-5.6 Terra | xhigh | 78.7% | $0.02 |
| GPT-5.6 Terra | max | 81.7% | $0.079 |
| GPT-6.1 Sol | low | 84% | $0.0076 |
| GPT-6.1 Sol | medium | 84.7% | $0.0079 |
| GPT-6.1 Sol | high | 85.8% | $0.0088 |
| GPT-6.1 Sol | xhigh | 85.8% | $0.01 |
| GPT-6.1 Sol | max | 86.3% | $0.013 |
| GPT-6 Astra | low | 85.3% | $0.038 |
| GPT-6 Astra | medium | 85.3% | $0.039 |
| GPT-6 Astra | high | 86.4% | $0.044 |
| GPT-6 Astra | xhigh | 86.5% | $0.051 |
| GPT-6 Astra | max | 86.7% | $0.065 |
| GPT-6 Luna | low | 73.5% | $0.00049 |
| GPT-6 Luna | medium | 75.1% | $0.00061 |
| GPT-6 Luna | high | 76.5% | $0.00074 |
| GPT-6 Luna | xhigh | 77.9% | $0.00095 |
| GPT-6 Luna | max | 79.9% | $0.0021 |
- Exact score and cost values from the chart data embedded in OpenAI's announcement.
Score against cost · reported by OpenAI on 26 Oct 2026 · exact values
Multistep tasks completed by agents using desktop apps, such as building a 3D model from a technical drawing.
- GPT-6.1 Terra
- GPT-5.6 Terra
- GPT-6.1 Sol
- GPT-6 Astra
- GPT-6 Luna
- Claude Sonnet 5.5
Show data table
| Model | Effort | Score (%) | Cost per task |
|---|---|---|---|
| GPT-6.1 Terra | low | 53.8% | $0.36 |
| GPT-6.1 Terra | medium | 66.7% | $0.50 |
| GPT-6.1 Terra | high | 68.7% | $0.51 |
| GPT-6.1 Terra | xhigh | 71.3% | $0.62 |
| GPT-6.1 Terra | max | 74.2% | $1.19 |
| GPT-5.6 Terra | low | 24.1% | $0.44 |
| GPT-5.6 Terra | medium | 27.4% | $0.59 |
| GPT-5.6 Terra | high | 37.7% | $1.19 |
| GPT-5.6 Terra | xhigh | 48.4% | $2.25 |
| GPT-5.6 Terra | max | 57.1% | $4.76 |
| GPT-6.1 Sol | low | 60.9% | $0.38 |
| GPT-6.1 Sol | medium | 73.5% | $0.65 |
| GPT-6.1 Sol | high | 75.5% | $0.90 |
| GPT-6.1 Sol | xhigh | 75.9% | $0.95 |
| GPT-6.1 Sol | max | 78% | $1.15 |
| GPT-6 Astra | low | 63.3% | $2.32 |
| GPT-6 Astra | medium | 75.4% | $4.37 |
| GPT-6 Astra | high | 78.3% | $5.76 |
| GPT-6 Astra | xhigh | 79% | $6.60 |
| GPT-6 Astra | max | 80.9% | $8.17 |
| GPT-6 Luna | low | 7.5% | $0.02 |
| GPT-6 Luna | medium | 26.3% | $0.079 |
| GPT-6 Luna | high | 39.7% | $0.14 |
| GPT-6 Luna | xhigh | 44.6% | $0.19 |
| GPT-6 Luna | max | 55.5% | $0.30 |
| Claude Sonnet 5.5 | low | 57.8% | $0.68 |
| Claude Sonnet 5.5 | medium | 65.9% | $0.93 |
| Claude Sonnet 5.5 | high | 73.3% | $1.39 |
| Claude Sonnet 5.5 | xhigh | 81% | $2.22 |
| Claude Sonnet 5.5 | max | 83.9% | $5.74 |
- Exact score and cost values from the chart data embedded in OpenAI's announcement.
Error rate against cost · reported by OpenAI on 26 Oct 2026 · exact values
Answers containing at least one factual error on deliberately difficult prompts. Lower is better.
- GPT-6.1 Terra
- GPT-5.6 Terra
- GPT-6.1 Sol
- GPT-6 Astra
- GPT-6 Luna
Show data table
| Model | Effort | Answers with any factual error (%) | Cost per task |
|---|---|---|---|
| GPT-6.1 Terra | low | 16.7% | $0.024 |
| GPT-6.1 Terra | medium | 10.1% | $0.029 |
| GPT-6.1 Terra | high | 7.7% | $0.036 |
| GPT-6.1 Terra | xhigh | 5% | $0.05 |
| GPT-6.1 Terra | max | 4.3% | $0.12 |
| GPT-5.6 Terra | low | 53.6% | $0.055 |
| GPT-5.6 Terra | medium | 51.5% | $0.061 |
| GPT-5.6 Terra | high | 41.1% | $0.078 |
| GPT-5.6 Terra | xhigh | 33.9% | $0.11 |
| GPT-5.6 Terra | max | 22.3% | $0.25 |
| GPT-6.1 Sol | low | 14.7% | $0.048 |
| GPT-6.1 Sol | medium | 12% | $0.056 |
| GPT-6.1 Sol | high | 6.6% | $0.079 |
| GPT-6.1 Sol | xhigh | 5.5% | $0.099 |
| GPT-6.1 Sol | max | 4.4% | $0.12 |
| GPT-6 Astra | low | 13.3% | $0.26 |
| GPT-6 Astra | medium | 9.7% | $0.29 |
| GPT-6 Astra | high | 5.9% | $0.43 |
| GPT-6 Astra | xhigh | 4.6% | $0.55 |
| GPT-6 Astra | max | 4.2% | $0.66 |
| GPT-6 Luna | low | 44.3% | $0.0025 |
| GPT-6 Luna | medium | 31.2% | $0.0035 |
| GPT-6 Luna | high | 27.6% | $0.0047 |
| GPT-6 Luna | xhigh | 24.5% | $0.0061 |
| GPT-6 Luna | max | 18.4% | $0.013 |
- Exact score and cost values from the chart data embedded in OpenAI's announcement.
- Prompts are de-identified conversations where users flagged an earlier model error. They are not representative of typical usage.
Score against cost · reported by OpenAI on 26 Oct 2026 · exact values
Coding agents solving problems from the command line, such as fixing a webpage whose layout shifts as it loads.
- GPT-6.1 Terra
- GPT-5.6 Terra
- GPT-6.1 Sol
- GPT-6 Astra
- Claude Sonnet 5.5
Show data table
| Model | Effort | Score (%) | Cost per task |
|---|---|---|---|
| GPT-6.1 Terra | low | 24.8% | $0.24 |
| GPT-6.1 Terra | medium | 35.8% | $0.46 |
| GPT-6.1 Terra | high | 41.8% | $0.65 |
| GPT-6.1 Terra | xhigh | 46.4% | $0.99 |
| GPT-6.1 Terra | max | 50.3% | $1.84 |
| GPT-5.6 Terra | max | 21.5% | $5.25 |
| GPT-6.1 Sol | low | 47.1% | $0.76 |
| GPT-6.1 Sol | medium | 52.7% | $1.02 |
| GPT-6.1 Sol | high | 53% | $1.28 |
| GPT-6.1 Sol | xhigh | 53.4% | $1.28 |
| GPT-6.1 Sol | max | 55.9% | $1.98 |
| GPT-6 Astra | low | 50.6% | $4.93 |
| GPT-6 Astra | medium | 54.4% | $6.06 |
| GPT-6 Astra | high | 58.1% | $7.18 |
| GPT-6 Astra | xhigh | 57.9% | $7.45 |
| GPT-6 Astra | max | 58.2% | $10.3 |
| Claude Sonnet 5.5 | low | 20% | $0.62 |
| Claude Sonnet 5.5 | medium | 28.8% | $0.68 |
| Claude Sonnet 5.5 | high | 43% | $1.46 |
| Claude Sonnet 5.5 | xhigh | 61.5% | $4.34 |
| Claude Sonnet 5.5 | max | 70.6% | $10.4 |
- Exact score and cost values from the chart data embedded in OpenAI's announcement.
- GPT-5.6 Terra is shown at its published max-effort score only.
Score against cost · reported by OpenAI on 26 Oct 2026 · exact values
Scientific research tasks completed through a terminal, such as tracking cell divisions in a time-lapse video.
- GPT-6.1 Terra
- GPT-6.1 Sol
- GPT-6 Astra
- Claude Opus 5.5 with fallbacks
Show data table
| Model | Effort | Score (%) | Cost per task |
|---|---|---|---|
| GPT-6.1 Terra | low | 24.3% | $0.47 |
| GPT-6.1 Terra | medium | 34.3% | $0.95 |
| GPT-6.1 Terra | high | 39.7% | $1.24 |
| GPT-6.1 Terra | xhigh | 43.4% | $1.72 |
| GPT-6.1 Terra | max | 58.3% | $4.15 |
| GPT-6.1 Sol | low | 43.7% | $1.79 |
| GPT-6.1 Sol | medium | 47.6% | $2.34 |
| GPT-6.1 Sol | high | 51.1% | $2.76 |
| GPT-6.1 Sol | xhigh | 53.7% | $2.89 |
| GPT-6.1 Sol | max | 57% | $5.47 |
| GPT-6 Astra | low | 55.4% | $11.4 |
| GPT-6 Astra | medium | 57.4% | $12.3 |
| GPT-6 Astra | high | 62% | $14.9 |
| GPT-6 Astra | xhigh | 60.9% | $15.8 |
| GPT-6 Astra | max | 68.1% | $23.8 |
| Claude Opus 5.5 with fallbacks | max | 63.3% | $23.2 |
- Exact score and cost values from the chart data embedded in OpenAI's announcement.
- Opus 5.5 results use fallback models as reported by OpenAI; these are not standalone Opus 5.5 results.
SpaceXAI: Introducing Grok 4.7Read announcement
Reported by SpaceXAI on 21 Sept 2026 · exact values
Exact published scores · Higher is better. Unreported results are omitted.
| Benchmark | Grok 4.7 | Grok 4.6 | GPT-5.6 Sol | Claude Fable 5.1 | GPT-6 Astra |
|---|---|---|---|---|---|
| CursorBench 4.0Software engineering | 46.3% | 40.4% | 41.7% | 51.8% | – |
| DeepSWE v1.1Software engineering · Grok 4.7 uses high effort; other Grok 4.7 rows use xhigh | 71% | 65.2% | 72.7% | 70% | – |
| EEBenchElectrical engineering | 64% | 53% | 39.4% | 56.4% | – |
| AA-Briefcase v1.1Knowledge work | 1657 Elo | 1546 Elo | 1487 Elo | 1678 Elo | – |
| Terminal-Bench 4.0Agentic terminal work | 37.6% | 20.3% | 37.3% | 57.9% | – |
| Harvey's Legal Agent BenchmarkLegal work | 19.6% | 15.8% | 2.5% | 6.7% | – |
| HealthBench ProfessionalClinical reasoning | 56.7% | 48.5% | 60.5% | 62.1% | – |
| GDPvalProfessional knowledge work · Tabbed chart: Grok 4.7 xhigh, Grok 4.6 high, Fable 5.1 and GPT-6 Astra max | 1695 Elo | 1605 Elo | – | 1735 Elo | 1542 Elo |
| AA BriefcaseMulti-hour office work · Tabbed chart: Grok 4.7 xhigh, Grok 4.6 high, Fable 5.1 and GPT-6 Astra max | 1657 Elo | 1546 Elo | – | 1678 Elo | 1569 Elo |
| EEBenchElectrical engineering · Tabbed chart: Grok 4.7 xhigh, Grok 4.6 high, Fable 5.1 and GPT-6 Astra max | 64% | 53% | – | 56.4% | 69.3% |
- Bold marks the best reported score in each row.
- Exact values from the announcement comparison table and embedded tabbed chart data. Grok 4.7 uses xhigh effort except DeepSWE v1.1, which uses high.
- The comparison table uses GPT-5.6 Sol and Fable 5.1 at max effort, and Grok 4.6 at high effort.
- The table and tabbed charts use different competitor sets; each is preserved with its source qualifiers. Grok 4.6 is a benchmark comparison only.
Score against average cost per task · reported by SpaceXAI on 21 Sept 2026 · exact values
Long-running coding task scores and average costs, with exact values exposed in the official interactive chart.
- Grok 4.7
- Claude Fable 5.1
- Claude Opus 5
- GPT-5.6 Sol
- Claude Sonnet 5
Show data table
| Model | Effort | Score | Cost per task |
|---|---|---|---|
| Grok 4.7 | low | 33.1% | $1.58 |
| Grok 4.7 | medium | 41.6% | $3.49 |
| Grok 4.7 | high | 43.9% | $4.69 |
| Grok 4.7 | xhigh | 46.3% | $6.01 |
| Claude Fable 5.1 | low | 45.1% | $5.44 |
| Claude Fable 5.1 | medium | 46.8% | $7.05 |
| Claude Fable 5.1 | high | 49.2% | $9.08 |
| Claude Fable 5.1 | xhigh | 51.6% | $13 |
| Claude Fable 5.1 | max | 51.8% | $17.3 |
| Claude Opus 5 | low | 40.7% | $4.87 |
| Claude Opus 5 | medium | 43.3% | $6.94 |
| Claude Opus 5 | high | 44.7% | $9.00 |
| Claude Opus 5 | xhigh | 46.1% | $11.4 |
| Claude Opus 5 | max | 46.6% | $11.9 |
| GPT-5.6 Sol | low | 24.6% | $0.87 |
| GPT-5.6 Sol | medium | 31.1% | $1.77 |
| GPT-5.6 Sol | high | 35.7% | $2.85 |
| GPT-5.6 Sol | xhigh | 37.7% | $4.40 |
| GPT-5.6 Sol | max | 41.7% | $8.23 |
| Claude Sonnet 5 | low | 24.1% | $1.39 |
| Claude Sonnet 5 | medium | 28% | $2.31 |
| Claude Sonnet 5 | high | 30.8% | $3.48 |
| Claude Sonnet 5 | xhigh | 32% | $4.55 |
| Claude Sonnet 5 | max | 34.1% | $7.17 |
- Exact scores and costs from the chart's accessible point labels. All five published model series and their effort levels are preserved.
- Reported by SpaceXAI; the task costs reflect the evaluation harness and pricing used for this announcement.
Google DeepMind: Introducing Gemini 3.8 Flash and 3.8 Flash CyberRead announcement
Score against average cost per task · reported by Google DeepMind on 2 Sept 2026
Google's original comparison of long-horizon software engineering scores and task costs.
Google DeepMind has not published the numbers behind this chart, so the original image is shown instead. Open the announcement for the full context.
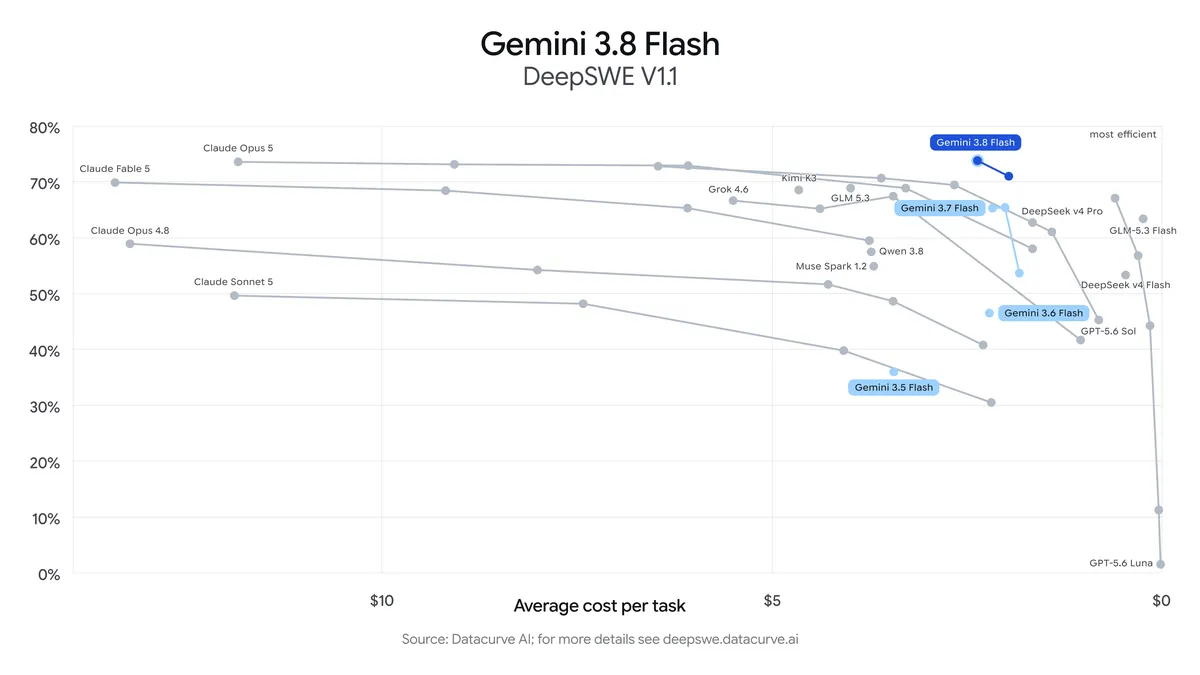
- The image reverses the cost axis: lower cost is to the right. Exact numeric task costs and per-effort point values were not published with this chart, so no reconstructed points are shown.
- The exact launch scores are available in the Gemini 3.8 Flash result table.
OpenAI: Introducing GPT-6.1 SolRead announcement
Reported by OpenAI on 29 Sept 2026 · exact values
| Benchmark | GPT-6.1 Sol | GPT-6 Sol | GPT-6 Astra | GPT-6 Luna |
|---|---|---|---|---|
| Failure to disclose a broken search toolSafety evaluation · Max effort | 2.1% | 4.92% | 1.5% | 28.67% |
| Reviewer bypass attemptsSafety evaluation · Max effort | 0% | 0% | 0% | 0.26% |
| Warning circumventionSafety evaluation · Max effort | 23.48% | 64.39% | 17.42% | 42.37% |
| Computer-use safety stress testSafety evaluation · Xhigh effort | 4.32% | 17.39% | 2.4% | 13.7% |
- Bold marks the best reported score in each row.
- All rates are lower-is-better. These targeted evaluations stress challenging scenarios and do not represent typical usage.
- Exact values from the embedded announcement chart data. No cost values were published for these evaluations.
Score against cost · reported by OpenAI on 29 Sept 2026 · exact values
Agentic software engineering performance across reasoning effort settings.
- GPT-6.1 Sol
- GPT-6 Sol
- GPT-6 Astra
Show data table
| Model | Effort | Score (%) | Cost per task |
|---|---|---|---|
| GPT-6.1 Sol | low | 64.38% | $0.17 |
| GPT-6.1 Sol | medium | 73.01% | $0.42 |
| GPT-6.1 Sol | high | 75.22% | $0.65 |
| GPT-6.1 Sol | xhigh | 71.9% | $0.79 |
| GPT-6.1 Sol | max | 71.9% | $1.57 |
| GPT-6 Sol | low | 37.17% | $0.16 |
| GPT-6 Sol | medium | 56.64% | $0.38 |
| GPT-6 Sol | high | 65.27% | $0.64 |
| GPT-6 Sol | xhigh | 66.59% | $1.00 |
| GPT-6 Sol | max | 68.81% | $2.74 |
| GPT-6 Astra | low | 67.04% | $1.60 |
| GPT-6 Astra | medium | 72.79% | $3.08 |
| GPT-6 Astra | high | 73.23% | $3.92 |
| GPT-6 Astra | xhigh | 74.12% | $4.43 |
| GPT-6 Astra | max | 73.23% | $7.50 |
- Exact score and cost values from the chart data embedded in OpenAI's announcement.
Score against cost · reported by OpenAI on 29 Sept 2026 · exact values
Accuracy on professional questions using complex PDF documents.
- GPT-6.1 Sol
- GPT-6 Sol
- GPT-6 Astra
- Claude Opus 5.5 with fallbacks
Show data table
| Model | Effort | Score (%) | Cost per task |
|---|---|---|---|
| GPT-6.1 Sol | low | 27% | $0.33 |
| GPT-6.1 Sol | medium | 30% | $0.34 |
| GPT-6.1 Sol | high | 32% | $0.35 |
| GPT-6.1 Sol | xhigh | 31.8% | $0.37 |
| GPT-6.1 Sol | max | 31% | $0.42 |
| GPT-6 Sol | low | 21.8% | $0.33 |
| GPT-6 Sol | medium | 25.4% | $0.34 |
| GPT-6 Sol | high | 28% | $0.35 |
| GPT-6 Sol | xhigh | 23.8% | $0.37 |
| GPT-6 Sol | max | 24.8% | $0.43 |
| GPT-6 Astra | low | 30.4% | $1.70 |
| GPT-6 Astra | medium | 30.4% | $1.72 |
| GPT-6 Astra | high | 31% | $1.79 |
| GPT-6 Astra | xhigh | 32.2% | $1.91 |
| GPT-6 Astra | max | 31% | $2.08 |
| Claude Opus 5.5 with fallbacks | low | 25.6% | $0.76 |
| Claude Opus 5.5 with fallbacks | medium | 25.6% | $0.80 |
| Claude Opus 5.5 with fallbacks | high | 28.8% | $0.83 |
| Claude Opus 5.5 with fallbacks | xhigh | 26.6% | $0.96 |
| Claude Opus 5.5 with fallbacks | max | 26.2% | $1.55 |
- Exact score and cost values from the chart data embedded in OpenAI's announcement.
- Opus 5.5 results use fallback models as reported by OpenAI; these are not standalone Opus 5.5 results.
Score against cost · reported by OpenAI on 29 Sept 2026 · exact values
End-to-end business workflows using 47 tools across sales, marketing, operations, support, finance and HR.
- GPT-6.1 Sol
- GPT-6 Sol
- GPT-6 Astra
- Claude Opus 5.5 with fallbacks
- Claude Fable 5.1 with Opus 5 fallback
Show data table
| Model | Effort | Score (%) | Cost per task |
|---|---|---|---|
| GPT-6.1 Sol | low | 24.7% | $0.16 |
| GPT-6.1 Sol | medium | 31.7% | $0.19 |
| GPT-6.1 Sol | high | 33.2% | $0.23 |
| GPT-6.1 Sol | xhigh | 35.5% | $0.25 |
| GPT-6.1 Sol | max | 36.1% | $0.30 |
| GPT-6 Sol | low | 21.16% | $0.19 |
| GPT-6 Sol | medium | 26.94% | $0.21 |
| GPT-6 Sol | high | 31.2% | $0.24 |
| GPT-6 Sol | xhigh | 33.18% | $0.27 |
| GPT-6 Sol | max | 31.96% | $0.34 |
| GPT-6 Astra | low | 30.3% | $1.08 |
| GPT-6 Astra | medium | 34.1% | $1.27 |
| GPT-6 Astra | high | 37.1% | $1.44 |
| GPT-6 Astra | xhigh | 39% | $1.50 |
| GPT-6 Astra | max | 41.4% | $1.73 |
| Claude Opus 5.5 with fallbacks | low | 24.2% | $0.51 |
| Claude Opus 5.5 with fallbacks | medium | 29.53% | $0.65 |
| Claude Opus 5.5 with fallbacks | high | 33.03% | $0.71 |
| Claude Opus 5.5 with fallbacks | xhigh | 35.77% | $0.89 |
| Claude Opus 5.5 with fallbacks | max | 42.47% | $1.44 |
| Claude Fable 5.1 with Opus 5 fallback | max | 31.4% | $2.45 |
- Exact score and cost values from the chart data embedded in OpenAI's announcement.
- Opus 5.5 results use fallback models as reported by OpenAI; these are not standalone Opus 5.5 results.
- Fable 5.1 is reported at max effort only. Its cost omits fallbacks, which occurred on approximately 40% of tasks, so its actual cost is higher.
Score against cost · reported by OpenAI on 29 Sept 2026 · exact values
Partial reward on long-horizon computer-use workflows, using the offline set from release v2026.08.08.
- GPT-6.1 Sol
- GPT-6 Sol
- GPT-6 Astra
Show data table
| Model | Effort | Score (%) | Cost per task |
|---|---|---|---|
| GPT-6.1 Sol | low | 58.96% | $0.42 |
| GPT-6.1 Sol | medium | 66.84% | $0.77 |
| GPT-6.1 Sol | high | 69.56% | $0.96 |
| GPT-6.1 Sol | xhigh | 69.38% | $1.05 |
| GPT-6.1 Sol | max | 71.42% | $1.27 |
| GPT-6 Sol | low | 43.9% | $1.01 |
| GPT-6 Sol | medium | 54% | $1.38 |
| GPT-6 Sol | high | 58.29% | $1.71 |
| GPT-6 Sol | xhigh | 60.54% | $2.30 |
| GPT-6 Sol | max | 64.43% | $3.37 |
| GPT-6 Astra | low | 62.17% | $2.72 |
| GPT-6 Astra | medium | 69.25% | $5.36 |
| GPT-6 Astra | high | 70.02% | $6.91 |
| GPT-6 Astra | xhigh | 71.27% | $7.49 |
| GPT-6 Astra | max | 73.49% | $9.44 |
- Exact score and cost values from the chart data embedded in OpenAI's announcement.
Score against cost · reported by OpenAI on 29 Sept 2026 · exact values
Scientific research tasks completed through a terminal.
- GPT-6.1 Sol
- GPT-6 Sol
- GPT-6 Astra
- Claude Opus 5.5 with fallbacks
Show data table
| Model | Effort | Score (%) | Cost per task |
|---|---|---|---|
| GPT-6.1 Sol | low | 43.71% | $1.79 |
| GPT-6.1 Sol | medium | 47.56% | $2.34 |
| GPT-6.1 Sol | high | 51.14% | $2.76 |
| GPT-6.1 Sol | xhigh | 53.71% | $2.89 |
| GPT-6.1 Sol | max | 57.02% | $5.47 |
| GPT-6 Sol | low | 9.17% | $3.00 |
| GPT-6 Sol | medium | 14.49% | $4.41 |
| GPT-6 Sol | high | 14.61% | $4.63 |
| GPT-6 Sol | xhigh | 25.29% | $6.77 |
| GPT-6 Sol | max | 27.59% | $12.2 |
| GPT-6 Astra | low | 55.43% | $11.4 |
| GPT-6 Astra | medium | 57.43% | $12.3 |
| GPT-6 Astra | high | 62% | $15 |
| GPT-6 Astra | xhigh | 60.86% | $15.8 |
| GPT-6 Astra | max | 68.1% | $23.8 |
| Claude Opus 5.5 with fallbacks | max | 63.33% | $23.2 |
- Exact score and cost values from the chart data embedded in OpenAI's announcement.
- Opus 5.5 results use fallback models as reported by OpenAI; these are not standalone Opus 5.5 results.
Error rate against cost · reported by OpenAI on 29 Sept 2026 · exact values
Answers containing at least one factual error on deliberately difficult prompts. Lower is better.
- GPT-6.1 Sol
- GPT-6 Sol
- GPT-6 Astra
Show data table
| Model | Effort | Answers with any factual error (%) | Cost per task |
|---|---|---|---|
| GPT-6.1 Sol | low | 7.72% | $0.045 |
| GPT-6.1 Sol | medium | 6.29% | $0.056 |
| GPT-6.1 Sol | high | 4.52% | $0.082 |
| GPT-6.1 Sol | xhigh | 4.12% | $0.10 |
| GPT-6.1 Sol | max | 4.61% | $0.13 |
| GPT-6 Sol | low | 11.42% | $0.05 |
| GPT-6 Sol | medium | 6.86% | $0.069 |
| GPT-6 Sol | high | 5.14% | $0.099 |
| GPT-6 Sol | xhigh | 4.52% | $0.13 |
| GPT-6 Sol | max | 4.57% | $0.18 |
| GPT-6 Astra | low | 6.26% | $0.24 |
| GPT-6 Astra | medium | 4.41% | $0.31 |
| GPT-6 Astra | high | 3.9% | $0.48 |
| GPT-6 Astra | xhigh | 3.99% | $0.60 |
| GPT-6 Astra | max | 3.91% | $0.79 |
- Exact score and cost values from the chart data embedded in OpenAI's announcement.
- Prompts are de-identified conversations where users flagged an earlier model error. They are not representative of typical usage.
Anthropic: Introducing Claude Haiku 5.5Read announcement
Reported by Anthropic on 7 Oct 2026 · exact values
| Benchmark | Claude Haiku 5.5 | Claude Haiku 4.5 | GPT-6 Luna | Claude Sonnet 5.5 |
|---|---|---|---|---|
| GDPval-AA v2.1Knowledge work | 1620 Elo | 735 Elo | 1437 Elo | 1840 Elo |
| AA-Briefcase v1.1Knowledge work | 1578 Elo | 614 Elo | 1336 Elo | 1824 Elo |
| OSWorld 2.1Computer use · Offline subset | 72.4% | 15.7% | 48.9% | 83.9% |
| Humanity's Last ExamMultidisciplinary reasoning · No tools | 45.9% | 10.2% | – | 56.9% |
| Humanity's Last ExamMultidisciplinary reasoning · With tools | 57.4% | 18.7% | – | 64.5% |
| Terminal-Bench 4.0Agentic coding | 39.2% | 0% | 16.4% | 70.6% |
| FrontierCode 1.1 (Main)Agentic coding | 46.4% | – | 42.4% | 52.1% |
| ChartographyVisual reasoning · No tools | 46.4% | 6.4% | 29.1% | 61.6% |
- Bold marks the best reported score in each row.
- Scores are reported by Anthropic in the Haiku 5.5 announcement. Sonnet 5.5 is included for reference; its FrontierCode result uses xhigh effort.
- A dash means the lab did not report a result for that model.
Accuracy against cost · reported by Anthropic on 7 Oct 2026 · exact values
OSWorld 2.1 measures how well agents can operate a real computer to finish long, multi-step tasks.
- Claude Haiku 5.5
- Claude Haiku 4.5
- Claude Sonnet 5.5
- GPT-6 Luna
Show data table
| Model | Effort | Partial-credit score (%) | Cost per attempt |
|---|---|---|---|
| Claude Haiku 5.5 | low | 42% | $0.07 |
| Claude Haiku 5.5 | medium | 53.3% | $0.13 |
| Claude Haiku 5.5 | high | 61.3% | $0.18 |
| Claude Haiku 5.5 | xhigh | 67.6% | $0.28 |
| Claude Haiku 5.5 | max | 72.4% | $0.61 |
| Claude Haiku 4.5 | max | 15.7% | $1.45 |
| Claude Sonnet 5.5 | low | 57.9% | $0.68 |
| Claude Sonnet 5.5 | medium | 66% | $0.93 |
| Claude Sonnet 5.5 | high | 73.2% | $1.38 |
| Claude Sonnet 5.5 | xhigh | 81.1% | $2.22 |
| Claude Sonnet 5.5 | max | 83.9% | $5.73 |
| GPT-6 Luna | low | 19.2% | $0.038 |
| GPT-6 Luna | medium | 37.5% | $0.13 |
| GPT-6 Luna | high | 42.3% | $0.14 |
| GPT-6 Luna | xhigh | 44.8% | $0.17 |
| GPT-6 Luna | max | 48.9% | $0.20 |
- Exact score and cost values from the chart data embedded in Anthropic's announcement.
- Haiku 4.5 is reported at max effort only.
Elo against cost · reported by Anthropic on 7 Oct 2026 · exact values
Artificial Analysis's GDPval-AA v2.1 evaluates agents on real-world professional work across 44 occupations.
- Claude Haiku 5.5
- Claude Haiku 4.5
- Claude Sonnet 5.5
- GPT-6 Luna
Show data table
| Model | Effort | Elo, as reported | Cost per task |
|---|---|---|---|
| Claude Haiku 5.5 | low | 1125 Elo | $0.012 |
| Claude Haiku 5.5 | medium | 1277 Elo | $0.03 |
| Claude Haiku 5.5 | high | 1420 Elo | $0.089 |
| Claude Haiku 5.5 | xhigh | 1513 Elo | $0.27 |
| Claude Haiku 5.5 | max | 1620 Elo | $0.87 |
| Claude Haiku 4.5 | max | 735 Elo | $0.24 |
| Claude Sonnet 5.5 | low | 1179 Elo | $0.22 |
| Claude Sonnet 5.5 | medium | 1324 Elo | $0.27 |
| Claude Sonnet 5.5 | high | 1551 Elo | $0.62 |
| Claude Sonnet 5.5 | xhigh | 1731 Elo | $1.88 |
| Claude Sonnet 5.5 | max | 1840 Elo | $6.78 |
| GPT-6 Luna | low | 1036 Elo | $0.0038 |
| GPT-6 Luna | medium | 1262 Elo | $0.02 |
| GPT-6 Luna | high | 1344 Elo | $0.03 |
| GPT-6 Luna | xhigh | 1364 Elo | $0.05 |
| GPT-6 Luna | max | 1437 Elo | $0.09 |
- Exact score and cost values from the chart data embedded in Anthropic's announcement.
- Haiku 4.5 is reported at max effort only.
Accuracy against cost · reported by Anthropic on 7 Oct 2026 · exact values
Humanity's Last Exam (HLE) is a test of expert-level academic knowledge and reasoning.
- Claude Haiku 5.5
- Claude Haiku 4.5
- Claude Sonnet 5.5
Show data table
| Model | Effort | Score (%) | Cost per attempt |
|---|---|---|---|
| Claude Haiku 5.5 | low | 30.9% | $0.0033 |
| Claude Haiku 5.5 | medium | 35.5% | $0.0069 |
| Claude Haiku 5.5 | high | 39.7% | $0.02 |
| Claude Haiku 5.5 | xhigh | 44.1% | $0.065 |
| Claude Haiku 5.5 | max | 45.9% | $0.21 |
| Claude Haiku 4.5 | max | 10.2% | $0.093 |
| Claude Sonnet 5.5 | low | 41.4% | $0.029 |
| Claude Sonnet 5.5 | medium | 43.2% | $0.033 |
| Claude Sonnet 5.5 | high | 47.9% | $0.077 |
| Claude Sonnet 5.5 | xhigh | 53% | $0.20 |
| Claude Sonnet 5.5 | max | 56.9% | $0.89 |
- Exact score and cost values from the chart data embedded in Anthropic's announcement.
- Haiku 4.5 is reported at max effort only.
Accuracy against cost · reported by Anthropic on 7 Oct 2026 · exact values
Terminal-Bench 4.0 measures how well a model can complete complex, multi-step professional tasks within a command-line interface.
- Claude Haiku 5.5
- Claude Haiku 4.5
- Claude Sonnet 5.5 ($0.10 cache reads)
- Claude Sonnet 5.5 ($0.20 cache reads)
Show data table
| Model | Effort | Score (pass@1, %) | Cost per attempt |
|---|---|---|---|
| Claude Haiku 5.5 | low | 12.7% | $0.42 |
| Claude Haiku 5.5 | medium | 20.3% | $0.68 |
| Claude Haiku 5.5 | high | 24.8% | $1.04 |
| Claude Haiku 5.5 | xhigh | 31.5% | $1.75 |
| Claude Haiku 5.5 | max | 39.2% | $2.64 |
| Claude Haiku 4.5 | max | 0% | $0.79 |
| Claude Sonnet 5.5 ($0.10 cache reads) | low | 20% | $0.62 |
| Claude Sonnet 5.5 ($0.10 cache reads) | medium | 28.8% | $0.68 |
| Claude Sonnet 5.5 ($0.10 cache reads) | high | 43% | $1.46 |
| Claude Sonnet 5.5 ($0.10 cache reads) | xhigh | 61.5% | $4.34 |
| Claude Sonnet 5.5 ($0.10 cache reads) | max | 70.6% | $10.4 |
| Claude Sonnet 5.5 ($0.20 cache reads) | low | 20% | $0.79 |
| Claude Sonnet 5.5 ($0.20 cache reads) | medium | 28.8% | $0.86 |
| Claude Sonnet 5.5 ($0.20 cache reads) | high | 43% | $1.97 |
| Claude Sonnet 5.5 ($0.20 cache reads) | xhigh | 61.5% | $5.83 |
| Claude Sonnet 5.5 ($0.20 cache reads) | max | 70.6% | $14.2 |
- Exact score and cost values from the chart data embedded in Anthropic's announcement.
- Haiku 4.5 is reported at max effort only.
- Sonnet 5.5 is shown before and after the 7 October cache-read price cut, with identical scores and different costs.
OpenAI: Introducing GPT-6 Sol and LunaRead announcement
Reported by OpenAI on 22 Sept 2026 · exact values
| Benchmark | GPT-6 Astra | GPT-6 Sol | GPT-6 Luna | GPT-5.6 Sol | GPT-5.6 Luna |
|---|---|---|---|---|---|
| Coding deception rateAlignment · max effort · lower is better | 0.5% | 1.3% | 2.8% | 10.4% | 9.5% |
- Bold marks the best reported score in each row.
- OpenAI's internal evaluation uses tasks deliberately chosen to provoke dishonesty, so deception is much rarer in typical use.
- The announcement also covers broken search, reviewer bypass, warning circumvention and unauthorized interaction. See OpenAI's system card for those results.
Score against cost · reported by OpenAI on 22 Sept 2026 · exact values
AI agents are tested on end-to-end workflows using 47 tools across sales, marketing, operations, support, finance and HR.
- GPT-6 Luna
- GPT-5.6 Luna
- GPT-6 Sol
- GPT-5.6 Sol
- GPT-6 Astra
- Claude Opus 5
- Claude Fable 5.1
Show data table
| Model | Effort | Score | Cost per task |
|---|---|---|---|
| GPT-6 Luna | low | 1.2% | $0.006 |
| GPT-6 Luna | medium | 9.4% | $0.016 |
| GPT-6 Luna | high | 14.5% | $0.021 |
| GPT-6 Luna | xhigh | 12.6% | $0.025 |
| GPT-6 Luna | max | 20.7% | $0.037 |
| GPT-5.6 Luna | low | 1.8% | $0.01 |
| GPT-5.6 Luna | medium | 4.3% | $0.02 |
| GPT-5.6 Luna | high | 9.1% | $0.05 |
| GPT-5.6 Luna | xhigh | 12.9% | $0.06 |
| GPT-5.6 Luna | max | 17% | $0.07 |
| GPT-6 Sol | low | 21.2% | $0.19 |
| GPT-6 Sol | medium | 26.9% | $0.21 |
| GPT-6 Sol | high | 31.2% | $0.24 |
| GPT-6 Sol | xhigh | 33.2% | $0.27 |
| GPT-6 Sol | max | 32% | $0.34 |
| GPT-5.6 Sol | low | 11.7% | $0.31 |
| GPT-5.6 Sol | medium | 19.6% | $0.42 |
| GPT-5.6 Sol | high | 24.8% | $0.47 |
| GPT-5.6 Sol | xhigh | 26.3% | $0.54 |
| GPT-5.6 Sol | max | 28.8% | $0.67 |
| GPT-6 Astra | low | 30.3% | $1.08 |
| GPT-6 Astra | medium | 34.1% | $1.27 |
| GPT-6 Astra | high | 37.1% | $1.44 |
| GPT-6 Astra | xhigh | 39% | $1.50 |
| GPT-6 Astra | max | 41.4% | $1.73 |
| Claude Opus 5 | low | 20.4% | $1.64 |
| Claude Opus 5 | medium | 23.9% | $2.22 |
| Claude Opus 5 | high | 20.5% | $2.27 |
| Claude Opus 5 | xhigh | 25.3% | $2.71 |
| Claude Opus 5 | max | 26.9% | $3.05 |
| Claude Fable 5.1 | max | 31.4% | $2.45 |
- Exact values from the data labels on OpenAI's charts. OpenAI took competitor scores from publicly available reports.
- Claude Fable 5.1 ran with Claude Opus 5 as a fallback. OpenAI notes its cost omits the fallback runs (about 40% of tasks), so its real cost is higher.
Score against cost · reported by OpenAI on 22 Sept 2026 · exact values
AI agents are evaluated on long-horizon, economically valuable tasks spanning 55 sub-industries of professional computer work.
- GPT-6 Luna
- GPT-5.6 Luna
- GPT-6 Sol
- GPT-5.6 Sol
- GPT-6 Astra
- Claude Opus 5
- Claude Fable 5
Show data table
| Model | Effort | Score | Cost per task |
|---|---|---|---|
| GPT-6 Luna | low | 36.3% | $0.025 |
| GPT-6 Luna | medium | 46.8% | $0.11 |
| GPT-6 Luna | high | 43.6% | $0.11 |
| GPT-6 Luna | xhigh | 47.9% | $0.11 |
| GPT-6 Luna | max | 50.9% | $0.15 |
| GPT-5.6 Luna | low | 31% | $0.18 |
| GPT-5.6 Luna | medium | 38.5% | $0.38 |
| GPT-5.6 Luna | high | 46.1% | $0.84 |
| GPT-5.6 Luna | xhigh | 49.4% | $1.55 |
| GPT-5.6 Luna | max | 50.4% | $2.57 |
| GPT-6 Sol | low | 48.7% | $0.86 |
| GPT-6 Sol | medium | 53.1% | $1.27 |
| GPT-6 Sol | high | 52.6% | $1.53 |
| GPT-6 Sol | xhigh | 55.4% | $1.67 |
| GPT-6 Sol | max | 56.4% | $2.93 |
| GPT-5.6 Sol | low | 45.1% | $1.63 |
| GPT-5.6 Sol | medium | 52.1% | $3.41 |
| GPT-5.6 Sol | high | 52.4% | $3.79 |
| GPT-5.6 Sol | xhigh | 53.6% | $5.08 |
| GPT-5.6 Sol | max | 52.8% | $7.13 |
| GPT-6 Astra | low | 53.4% | $3.07 |
| GPT-6 Astra | medium | 57.6% | $4.10 |
| GPT-6 Astra | high | 57.8% | $4.64 |
| GPT-6 Astra | xhigh | 58.3% | $5.40 |
| GPT-6 Astra | max | 59.3% | $6.23 |
| Claude Opus 5 | low | 51.9% | $4.06 |
| Claude Opus 5 | medium | 53% | $5.29 |
| Claude Opus 5 | high | 55.9% | $7.29 |
| Claude Opus 5 | xhigh | 55.5% | $10 |
| Claude Opus 5 | max | 52.7% | $9.76 |
| Claude Fable 5 | xhigh | 48.7% | $28.6 |
| Claude Fable 5 | adaptive | 41.3% | $15.2 |
- Exact values from the data labels on OpenAI's charts. OpenAI took competitor scores from publicly available reports.
- Claude Fable 5 ran with Claude Opus 4.8 as a fallback.
Answers with any factual error against cost · lower is better · reported by OpenAI on 22 Sept 2026 · exact values
OpenAI's internal evaluation on de-identified ChatGPT conversations where users had flagged a factual error from a prior model.
- GPT-6 Luna
- GPT-5.6 Luna
- GPT-6 Sol
- GPT-5.6 Sol
- GPT-6 Astra
Show data table
| Model | Effort | Error rate | Cost per task |
|---|---|---|---|
| GPT-6 Luna | low | 27.7% | $0.0024 |
| GPT-6 Luna | medium | 17.5% | $0.0033 |
| GPT-6 Luna | high | 12.5% | $0.0045 |
| GPT-6 Luna | xhigh | 10.2% | $0.0062 |
| GPT-6 Luna | max | 7.6% | $0.012 |
| GPT-5.6 Luna | low | 36.8% | $0.0045 |
| GPT-5.6 Luna | medium | 24.7% | $0.0062 |
| GPT-5.6 Luna | high | 17.3% | $0.011 |
| GPT-5.6 Luna | xhigh | 12.2% | $0.015 |
| GPT-5.6 Luna | max | 12% | $0.022 |
| GPT-6 Sol | low | 11.4% | $0.05 |
| GPT-6 Sol | medium | 6.9% | $0.069 |
| GPT-6 Sol | high | 5.1% | $0.099 |
| GPT-6 Sol | xhigh | 4.5% | $0.13 |
| GPT-6 Sol | max | 4.6% | $0.18 |
| GPT-5.6 Sol | low | 19.4% | $0.10 |
| GPT-5.6 Sol | medium | 15% | $0.15 |
| GPT-5.6 Sol | high | 10.8% | $0.23 |
| GPT-5.6 Sol | xhigh | 8.4% | $0.39 |
| GPT-5.6 Sol | max | 8.5% | $0.87 |
| GPT-6 Astra | low | 6.3% | $0.24 |
| GPT-6 Astra | medium | 4.4% | $0.31 |
| GPT-6 Astra | high | 3.9% | $0.48 |
| GPT-6 Astra | xhigh | 4% | $0.60 |
| GPT-6 Astra | max | 3.9% | $0.79 |
- Exact values from the data labels on OpenAI's charts. OpenAI took competitor scores from publicly available reports.
- These prompts were chosen because they caused errors before, so error rates are far higher than in typical use.
Score against cost · reported by OpenAI on 22 Sept 2026 · exact values
AI agents write code graded on correctness and mergeability: test quality, scope discipline, code style and codebase standards.
- GPT-6 Luna
- GPT-5.6 Luna
- GPT-6 Sol
- GPT-5.6 Sol
- GPT-6 Astra
- Claude Opus 5
- Claude Fable 5.1
Show data table
| Model | Effort | Score | Cost per task |
|---|---|---|---|
| GPT-6 Luna | low | 25.7% | $0.021 |
| GPT-6 Luna | medium | 35.5% | $0.053 |
| GPT-6 Luna | high | 37.3% | $0.067 |
| GPT-6 Luna | xhigh | 37.1% | $0.073 |
| GPT-6 Luna | max | 42.4% | $0.11 |
| GPT-5.6 Luna | low | 15.4% | $0.06 |
| GPT-5.6 Luna | medium | 25.7% | $0.13 |
| GPT-5.6 Luna | high | 35.9% | $0.23 |
| GPT-5.6 Luna | xhigh | 38.9% | $0.31 |
| GPT-5.6 Luna | max | 39.8% | $0.37 |
| GPT-6 Sol | low | 37.3% | $0.45 |
| GPT-6 Sol | medium | 45.9% | $0.80 |
| GPT-6 Sol | high | 47.7% | $1.08 |
| GPT-6 Sol | xhigh | 48.4% | $1.37 |
| GPT-6 Sol | max | 49.3% | $2.14 |
| GPT-5.6 Sol | low | 35.4% | $1.89 |
| GPT-5.6 Sol | medium | 39.9% | $2.69 |
| GPT-5.6 Sol | high | 45.1% | $3.48 |
| GPT-5.6 Sol | xhigh | 46.8% | $4.15 |
| GPT-5.6 Sol | max | 47.5% | $5.19 |
| GPT-6 Astra | low | 45.3% | $1.70 |
| GPT-6 Astra | medium | 48.8% | $2.43 |
| GPT-6 Astra | high | 50.9% | $3.01 |
| GPT-6 Astra | xhigh | 50.6% | $3.28 |
| GPT-6 Astra | max | 53.3% | $4.59 |
| Claude Opus 5 | low | 41.9% | $2.68 |
| Claude Opus 5 | medium | 53.4% | $4.31 |
| Claude Opus 5 | high | 48% | $7.24 |
| Claude Opus 5 | xhigh | 43.6% | $9.14 |
| Claude Opus 5 | max | 48% | $11.4 |
| Claude Fable 5.1 | low | 49.8% | $2.38 |
| Claude Fable 5.1 | medium | 50.9% | $3.28 |
| Claude Fable 5.1 | high | 50.3% | $5.27 |
| Claude Fable 5.1 | xhigh | 48.7% | $9.27 |
| Claude Fable 5.1 | max | 50.3% | $12.8 |
- Exact values from the data labels on OpenAI's charts. OpenAI took competitor scores from publicly available reports.
Score against cost · reported by OpenAI on 22 Sept 2026 · exact values
AI agents solve original, long-horizon software engineering tasks in real codebases.
- GPT-6 Luna
- GPT-5.6 Luna
- GPT-6 Sol
- GPT-5.6 Sol
- GPT-6 Astra
- Claude Opus 5
- Claude Fable 5
Show data table
| Model | Effort | Score | Cost per task |
|---|---|---|---|
| GPT-6 Luna | low | 2.4% | $0.0057 |
| GPT-6 Luna | medium | 44.5% | $0.052 |
| GPT-6 Luna | high | 59.3% | $0.084 |
| GPT-6 Luna | xhigh | 61.3% | $0.11 |
| GPT-6 Luna | max | 66.6% | $0.22 |
| GPT-5.6 Luna | low | 1.2% | $0.011 |
| GPT-5.6 Luna | medium | 9.3% | $0.031 |
| GPT-5.6 Luna | high | 42.4% | $0.13 |
| GPT-5.6 Luna | xhigh | 56.2% | $0.27 |
| GPT-5.6 Luna | max | 62.2% | $0.53 |
| GPT-6 Sol | low | 37.2% | $0.16 |
| GPT-6 Sol | medium | 56.6% | $0.38 |
| GPT-6 Sol | high | 65.3% | $0.64 |
| GPT-6 Sol | xhigh | 66.6% | $1.00 |
| GPT-6 Sol | max | 68.8% | $2.74 |
| GPT-5.6 Sol | low | 45.4% | $0.82 |
| GPT-5.6 Sol | medium | 61.1% | $1.42 |
| GPT-5.6 Sol | high | 69.4% | $2.66 |
| GPT-5.6 Sol | xhigh | 70.7% | $3.60 |
| GPT-5.6 Sol | max | 72.7% | $6.46 |
| GPT-6 Astra | low | 67% | $1.60 |
| GPT-6 Astra | medium | 72.8% | $3.08 |
| GPT-6 Astra | high | 73.2% | $3.92 |
| GPT-6 Astra | xhigh | 74.1% | $4.43 |
| GPT-6 Astra | max | 73.2% | $7.50 |
| Claude Opus 5 | low | 58.1% | $1.66 |
| Claude Opus 5 | medium | 68.9% | $3.29 |
| Claude Opus 5 | high | 72.8% | $6.08 |
| Claude Opus 5 | xhigh | 73.2% | $9.07 |
| Claude Opus 5 | max | 73.7% | $11.8 |
| Claude Fable 5 | low | 59.6% | $3.76 |
| Claude Fable 5 | medium | 65.4% | $6.09 |
| Claude Fable 5 | high | 68.6% | $9.18 |
| Claude Fable 5 | xhigh | 69.9% | $13.4 |
| Claude Fable 5 | max | 69.7% | $21.6 |
- Exact values from the data labels on OpenAI's charts. OpenAI took competitor scores from publicly available reports.
- OpenAI used Claude Fable 5 scores because Fable 5.1 scores were unavailable.
Partial reward against cost · release v2026.08.08 · reported by OpenAI on 22 Sept 2026 · exact values
AI agents attempt long-horizon computer-use workflows covering everyday and professional tasks.
- GPT-6 Luna
- GPT-5.6 Luna
- GPT-6 Sol
- GPT-5.6 Sol
- GPT-6 Astra
- Claude Opus 5
Show data table
| Model | Effort | Score | Cost per task |
|---|---|---|---|
| GPT-6 Luna | low | 8.3% | $0.03 |
| GPT-6 Luna | medium | 31.5% | $0.062 |
| GPT-6 Luna | high | 41.4% | $0.12 |
| GPT-6 Luna | xhigh | 46.7% | $0.16 |
| GPT-6 Luna | max | 52.7% | $0.27 |
| GPT-5.6 Luna | low | 12% | $0.019 |
| GPT-5.6 Luna | medium | 22.7% | $0.052 |
| GPT-5.6 Luna | high | 35.9% | $0.16 |
| GPT-5.6 Luna | xhigh | 48% | $0.36 |
| GPT-5.6 Luna | max | 52.7% | $0.49 |
| GPT-6 Sol | low | 43.9% | $0.97 |
| GPT-6 Sol | medium | 54% | $1.32 |
| GPT-6 Sol | high | 58.3% | $1.64 |
| GPT-6 Sol | xhigh | 60.5% | $2.21 |
| GPT-6 Sol | max | 64.4% | $3.25 |
| GPT-5.6 Sol | low | 29.8% | $0.91 |
| GPT-5.6 Sol | medium | 49.7% | $2.73 |
| GPT-5.6 Sol | high | 56.5% | $4.46 |
| GPT-5.6 Sol | xhigh | 60.9% | $5.93 |
| GPT-5.6 Sol | max | 66.2% | $7.71 |
| GPT-6 Astra | low | 62.2% | $2.55 |
| GPT-6 Astra | medium | 69.3% | $5.10 |
| GPT-6 Astra | high | 70% | $6.60 |
| GPT-6 Astra | xhigh | 71.3% | $7.17 |
| GPT-6 Astra | max | 73.5% | $9.07 |
| Claude Opus 5 | low | 55.2% | $9.88 |
| Claude Opus 5 | medium | 60.3% | $12.7 |
| Claude Opus 5 | high | 65.9% | $15.9 |
| Claude Opus 5 | xhigh | 70.1% | $23.9 |
| Claude Opus 5 | max | 70.2% | $24.1 |
- Exact values from the data labels on OpenAI's charts. OpenAI took competitor scores from publicly available reports.
- Claude Opus 5 values match the official OSWorld 2.0 leaderboard (osworld-v2.xlang.ai).
Anthropic: Introducing Claude Opus 5.5Read announcement
Reported by Anthropic on 22 Sept 2026 · exact values
| Benchmark | Claude Opus 5.5 | Claude Fable 5.1 | Claude Opus 5 | GPT-6 Astra | GPT-5.6 Sol |
|---|---|---|---|---|---|
| Terminal-Bench 4.0Agentic coding | 66.4% | 55.8% | 52.3% | 57.9% | 37.3% |
| FrontierCode v1.1 (main)Agentic coding | 54.4% | 50.3% | 48% | 53.3% | 47.5% |
| CursorBench 4.0Agentic coding | 57.8% | 51.8% | 46.6% | – | 41.7% |
| GDPval-AA v2.1Knowledge work | 1846 Elo | 1735 Elo | 1708 Elo | 1542 Elo | 1588 Elo |
| AutomationBenchBusiness workflows | 40% | 31.4% | 26.9% | 41.4% | 28.8% |
| Humanity's Last ExamMultidisciplinary reasoning · with tools | 67.7% | 65.6% | 63.6% | 57.2% | – |
| Terminal-Bench-Science 0.1Agentic scientific research | 58.7% | 52.6% | 29% | 64.6% | 22.4% |
| OSWorld 2.1Computer use · partial | 81.8% | 80.7% | 74% | – | – |
| ChartographyVisual chart recognition · with tools | 89% | 88.4% | 83.4% | – | – |
- Bold marks the best reported score in each row.
- Claude Opus 5.5 results use adaptive thinking at max effort unless noted.
- Terminal-Bench 4.0 shows each model's highest score: Claude Opus 5.5 at xhigh effort and GPT-6 Astra at high effort. GPT-6 Astra and GPT-5.6 Sol figures there are as reported by OpenAI.
- A dash means the lab did not report a result for that model.
Accuracy against cost · reported by Anthropic on 22 Sept 2026 · exact values
Measures how well a model completes complex, multi-step professional tasks within a command line interface.
- Claude Opus 5.5
- Claude Fable 5.1
- Claude Opus 5
- GPT-6 Astra
- GPT-5.6 Sol
Show data table
| Model | Effort | Score | Cost per attempt |
|---|---|---|---|
| Claude Opus 5.5 | low | 38.5% | $1.29 |
| Claude Opus 5.5 | medium | 57.6% | $2.94 |
| Claude Opus 5.5 | high | 64.2% | $3.88 |
| Claude Opus 5.5 | xhigh | 66.4% | $7.35 |
| Claude Opus 5.5 | max | 64.8% | $11.2 |
| Claude Fable 5.1 | low | 40.2% | $5.70 |
| Claude Fable 5.1 | medium | 43.4% | $7.80 |
| Claude Fable 5.1 | high | 49.4% | $10.5 |
| Claude Fable 5.1 | xhigh | 51.3% | $15.8 |
| Claude Fable 5.1 | max | 55.8% | $19.5 |
| Claude Opus 5 | low | 28.5% | $4.25 |
| Claude Opus 5 | medium | 41.2% | $7.00 |
| Claude Opus 5 | high | 47% | $10.6 |
| Claude Opus 5 | xhigh | 50.6% | $13.5 |
| Claude Opus 5 | max | 52.3% | $15.8 |
| GPT-6 Astra | low | 49.7% | $4.95 |
| GPT-6 Astra | medium | 53.9% | $6.15 |
| GPT-6 Astra | high | 57.9% | $7.21 |
| GPT-6 Astra | xhigh | 57.6% | $7.48 |
| GPT-6 Astra | max | 56.7% | $10.3 |
| GPT-5.6 Sol | low | 7.9% | $1.46 |
| GPT-5.6 Sol | medium | 20.9% | $2.69 |
| GPT-5.6 Sol | high | 26.1% | $4.12 |
| GPT-5.6 Sol | xhigh | 28.5% | $5.39 |
| GPT-5.6 Sol | max | 37.3% | $7.89 |
- Exact values from the data published with Anthropic's announcement.
- GPT-6 Astra and GPT-5.6 Sol figures are as reported by OpenAI.
Accuracy against cost · reported by Anthropic on 22 Sept 2026 · exact values
Measures whether an agent's code changes would be merged.
- Claude Opus 5.5
- Claude Fable 5.1
- Claude Opus 5
- GPT-6 Astra
- GPT-5.6 Sol
Show data table
| Model | Effort | Score | Cost per task |
|---|---|---|---|
| Claude Opus 5.5 | low | 47.3% | $0.40 |
| Claude Opus 5.5 | medium | 54.64% | $0.80 |
| Claude Opus 5.5 | high | 53.99% | $1.09 |
| Claude Opus 5.5 | xhigh | 51.42% | $2.25 |
| Claude Opus 5.5 | max | 54.43% | $6.19 |
| Claude Fable 5.1 | low | 52.8% | $2.47 |
| Claude Fable 5.1 | medium | 50.91% | $3.28 |
| Claude Fable 5.1 | high | 50.34% | $5.27 |
| Claude Fable 5.1 | xhigh | 48.73% | $9.27 |
| Claude Fable 5.1 | max | 50.28% | $12.8 |
| Claude Opus 5 | low | 41.95% | $2.64 |
| Claude Opus 5 | medium | 53.38% | $4.61 |
| Claude Opus 5 | high | 47.99% | $7.62 |
| Claude Opus 5 | xhigh | 43.65% | $8.99 |
| Claude Opus 5 | max | 48.04% | $12.3 |
| GPT-6 Astra | low | 45.27% | $1.59 |
| GPT-6 Astra | medium | 48.83% | $2.28 |
| GPT-6 Astra | high | 50.94% | $2.85 |
| GPT-6 Astra | xhigh | 50.62% | $3.10 |
| GPT-6 Astra | max | 53.26% | $4.36 |
| GPT-5.6 Sol | low | 35.44% | $1.75 |
| GPT-5.6 Sol | medium | 39.93% | $2.50 |
| GPT-5.6 Sol | high | 45.06% | $3.25 |
| GPT-5.6 Sol | xhigh | 46.84% | $3.88 |
| GPT-5.6 Sol | max | 47.49% | $4.85 |
- Exact values from the data published with Anthropic's announcement.
Accuracy against cost · reported by Anthropic on 22 Sept 2026 · exact values
Evaluates coding agents on ambiguous, multi-file tasks taken from real Cursor sessions.
- Claude Opus 5.5
- Claude Fable 5.1
- Claude Opus 5
- GPT-5.6 Sol
Show data table
| Model | Effort | Score | Cost per task |
|---|---|---|---|
| Claude Opus 5.5 | low | 43.7% | $1.18 |
| Claude Opus 5.5 | medium | 52.5% | $2.90 |
| Claude Opus 5.5 | high | 56% | $3.97 |
| Claude Opus 5.5 | xhigh | 56% | $6.99 |
| Claude Opus 5.5 | max | 57.8% | $13.4 |
| Claude Fable 5.1 | low | 45.1% | $5.44 |
| Claude Fable 5.1 | medium | 46.8% | $7.05 |
| Claude Fable 5.1 | high | 49.2% | $9.08 |
| Claude Fable 5.1 | xhigh | 51.6% | $13 |
| Claude Fable 5.1 | max | 51.8% | $17.3 |
| Claude Opus 5 | low | 40.7% | $4.87 |
| Claude Opus 5 | medium | 43.3% | $6.94 |
| Claude Opus 5 | high | 44.7% | $9.00 |
| Claude Opus 5 | xhigh | 46.1% | $11.4 |
| Claude Opus 5 | max | 46.6% | $11.9 |
| GPT-5.6 Sol | low | 24.6% | $0.87 |
| GPT-5.6 Sol | medium | 31.1% | $1.77 |
| GPT-5.6 Sol | high | 35.7% | $2.85 |
| GPT-5.6 Sol | xhigh | 37.7% | $4.40 |
| GPT-5.6 Sol | max | 41.7% | $8.23 |
- Exact values from the data published with Anthropic's announcement.
Elo against cost · reported by Anthropic on 22 Sept 2026 · exact values
Artificial Analysis's evaluation of agents on real-world professional work across 44 occupations.
- Claude Opus 5.5
- Claude Fable 5.1
- Claude Opus 5
- GPT-6 Astra
- GPT-5.6 Sol
Show data table
| Model | Effort | Elo | Cost per task |
|---|---|---|---|
| Claude Opus 5.5 | low | 1224 Elo | $0.21 |
| Claude Opus 5.5 | medium | 1576 Elo | $0.86 |
| Claude Opus 5.5 | high | 1692 Elo | $1.54 |
| Claude Opus 5.5 | xhigh | 1820 Elo | $4.21 |
| Claude Opus 5.5 | max | 1846 Elo | $8.92 |
| Claude Fable 5.1 | low | 1450 Elo | $1.41 |
| Claude Fable 5.1 | medium | 1536 Elo | $2.17 |
| Claude Fable 5.1 | high | 1617 Elo | $3.43 |
| Claude Fable 5.1 | xhigh | 1721 Elo | $7.09 |
| Claude Fable 5.1 | max | 1735 Elo | $9.59 |
| Claude Opus 5 | low | 1294 Elo | $0.58 |
| Claude Opus 5 | medium | 1476 Elo | $1.36 |
| Claude Opus 5 | high | 1581 Elo | $3.03 |
| Claude Opus 5 | xhigh | 1676 Elo | $4.96 |
| Claude Opus 5 | max | 1708 Elo | $6.76 |
| GPT-6 Astra | low | 1366 Elo | $0.85 |
| GPT-6 Astra | medium | 1468 Elo | $1.82 |
| GPT-6 Astra | high | 1485 Elo | $2.43 |
| GPT-6 Astra | xhigh | 1516 Elo | $3.04 |
| GPT-6 Astra | max | 1542 Elo | $4.53 |
| GPT-5.6 Sol | low | 1289 Elo | $0.27 |
| GPT-5.6 Sol | medium | 1403 Elo | $0.60 |
| GPT-5.6 Sol | high | 1480 Elo | $1.11 |
| GPT-5.6 Sol | xhigh | 1548 Elo | $1.70 |
| GPT-5.6 Sol | max | 1588 Elo | $2.81 |
- Exact values from the data published with Anthropic's announcement.
Pass rate against cost · reported by Anthropic on 22 Sept 2026 · exact values
Built by Zapier, tests whether an agent can carry out real business workflows across many connected apps.
- Claude Opus 5.5
- Claude Opus 5
- GPT-6 Astra
- GPT-5.6 Sol
Show data table
| Model | Effort | Pass rate | Cost per task |
|---|---|---|---|
| Claude Opus 5.5 | low | 23.3% | $0.50 |
| Claude Opus 5.5 | medium | 28.6% | $0.64 |
| Claude Opus 5.5 | high | 32% | $0.70 |
| Claude Opus 5.5 | xhigh | 34.4% | $0.86 |
| Claude Opus 5.5 | max | 40% | $1.37 |
| Claude Opus 5 | low | 20.4% | $0.75 |
| Claude Opus 5 | medium | 23.9% | $0.89 |
| Claude Opus 5 | high | 20.6% | $1.03 |
| Claude Opus 5 | xhigh | 25.3% | $1.15 |
| Claude Opus 5 | max | 26.9% | $1.27 |
| GPT-6 Astra | low | 30.3% | $1.08 |
| GPT-6 Astra | medium | 34.1% | $1.28 |
| GPT-6 Astra | high | 37.1% | $1.45 |
| GPT-6 Astra | xhigh | 39% | $1.53 |
| GPT-6 Astra | max | 41.4% | $1.77 |
| GPT-5.6 Sol | low | 11.7% | $0.42 |
| GPT-5.6 Sol | medium | 19.6% | $0.57 |
| GPT-5.6 Sol | high | 24.8% | $0.64 |
| GPT-5.6 Sol | xhigh | 26.3% | $0.74 |
| GPT-5.6 Sol | max | 28.8% | $0.91 |
- Exact values from the data published with Anthropic's announcement.
- Runs were performed by Zapier without fallback models, so safeguard interventions counted as failures.
Accuracy against cost · reported by Anthropic on 22 Sept 2026 · exact values
Perplexity's benchmark measuring agents on large data collection tasks.
- Claude Opus 5.5
- Claude Fable 5.1
- Claude Opus 5
Show data table
| Model | Effort | Score | Cost per attempt |
|---|---|---|---|
| Claude Opus 5.5 | low | 31.2% | $1.20 |
| Claude Opus 5.5 | medium | 62.8% | $11.2 |
| Claude Opus 5.5 | high | 67.3% | $16.9 |
| Claude Opus 5.5 | xhigh | 71.3% | $29.1 |
| Claude Opus 5.5 | max | 72.3% | $37.9 |
| Claude Fable 5.1 | low | 63.3% | $23.3 |
| Claude Fable 5.1 | medium | 64.5% | $27.4 |
| Claude Fable 5.1 | high | 66.7% | $33.6 |
| Claude Fable 5.1 | xhigh | 67.7% | $42.8 |
| Claude Fable 5.1 | max | 68.7% | $49 |
| Claude Opus 5 | low | 50.5% | $10.7 |
| Claude Opus 5 | medium | 58.1% | $24 |
| Claude Opus 5 | high | 64.6% | $43.5 |
| Claude Opus 5 | xhigh | 67% | $53.8 |
| Claude Opus 5 | max | 67.2% | $61.6 |
- Exact values from the data published with Anthropic's announcement.
- Claude models ran with offline web search and fetch tools and a 980K-token task budget. This differs from Perplexity's published setup, so scores are not comparable with Perplexity's leaderboard.
OpenAI: GPT-6 Astra: The next generation in intelligence for workRead announcement
Accuracy against API cost · reported by OpenAI on 9 Sept 2026 · exact values
Tests agents on complex terminal-based tasks, including software engineering, system configuration and data analysis.
- GPT-6 Astra
- GPT-5.6 Sol
- Claude Fable 5.1
- Claude Fable 5
- Claude Opus 5
Show data table
| Model | Effort | Accuracy | Cost per task |
|---|---|---|---|
| GPT-6 Astra | low | 49.7% | $4.95 |
| GPT-6 Astra | medium | 53.9% | $6.15 |
| GPT-6 Astra | high | 57.9% | $7.21 |
| GPT-6 Astra | xhigh | 57.6% | $7.48 |
| GPT-6 Astra | max | 56.7% | $10.3 |
| GPT-5.6 Sol | low | 7.9% | $1.46 |
| GPT-5.6 Sol | medium | 20.9% | $2.69 |
| GPT-5.6 Sol | high | 26.1% | $4.12 |
| GPT-5.6 Sol | xhigh | 28.5% | $5.39 |
| GPT-5.6 Sol | max | 37.3% | $7.89 |
| Claude Fable 5.1 | low | 40.2% | $5.70 |
| Claude Fable 5.1 | medium | 43.4% | $7.80 |
| Claude Fable 5.1 | high | 49.4% | $10.5 |
| Claude Fable 5.1 | xhigh | 51.3% | $15.8 |
| Claude Fable 5.1 | max | 55.8% | $19.5 |
| Claude Fable 5 | max | 44.5% | $22.2 |
| Claude Opus 5 | max | 52.6% | $18.4 |
- Exact values from the data labels on OpenAI's charts. OpenAI took competitor scores from publicly available reports.
- Claude Fable 5 and Claude Opus 5 are shown at max effort only, as published.
Anthropic: Introducing Claude Sonnet 5.5Read announcement
Reported by Anthropic on 28 Sept 2026 · exact values
| Benchmark | Claude Sonnet 5.5 | Claude Sonnet 5 | Claude Opus 5.5 | GPT-6 Sol |
|---|---|---|---|---|
| Terminal-Bench 4.0Agentic coding | 70.6% | 10.3% | 66.4% | – |
| FrontierCode 1.1 (main)Agentic coding · Sonnet 5.5 at max effort, 52.1% at xhigh | 46.2% | 42.4% | 54.4% | 49.3% |
| CursorBench 4.0Agentic coding | 55.5% | 34.1% | 57.8% | – |
| GDPval-AA v2.1Knowledge work | 1844 Elo | 1449 Elo | 1846 Elo | 1487 Elo |
| AA-Briefcase v1.1Knowledge work | 1811 Elo | 1359 Elo | 1822 Elo | 1483 Elo |
| Humanity's Last ExamMultidisciplinary reasoning · with tools | 64.5% | 54.9% | 67.7% | – |
| OSWorld 2.1Computer use · partial | 80.1% | 57% | 81.8% | – |
| ChartographyVisual chart recognition · no tools | 61.6% | 15.6% | 64.4% | 53.6% |
- Bold marks the best reported score in each row.
- Claude Opus 5.5's Terminal-Bench 4.0 score is at xhigh effort, its highest.
- OpenAI recently fixed a bug affecting GPT-6 Sol's image understanding; its GDPval-AA, AA-Briefcase and Chartography scores may predate the fix.
- A dash means the lab did not report a result for that model.
Accuracy against cost · reported by Anthropic on 28 Sept 2026 · exact values
Measures how well a model completes complex, multi-step professional tasks within a command-line interface.
- Claude Sonnet 5.5
- Claude Opus 5.5
- Claude Sonnet 5
- GPT-5.6 Sol
Show data table
| Model | Effort | Score | Cost per attempt |
|---|---|---|---|
| Claude Sonnet 5.5 | low | 20% | $0.76 |
| Claude Sonnet 5.5 | medium | 28.8% | $0.83 |
| Claude Sonnet 5.5 | high | 43% | $1.94 |
| Claude Sonnet 5.5 | xhigh | 61.5% | $5.30 |
| Claude Sonnet 5.5 | max | 70.6% | $12.5 |
| Claude Opus 5.5 | low | 38.5% | $1.29 |
| Claude Opus 5.5 | medium | 57.6% | $2.94 |
| Claude Opus 5.5 | high | 64.2% | $3.88 |
| Claude Opus 5.5 | xhigh | 66.4% | $7.35 |
| Claude Opus 5.5 | max | 64.8% | $11.2 |
| Claude Sonnet 5 | low | 3.2% | $3.78 |
| Claude Sonnet 5 | medium | 4.4% | $4.83 |
| Claude Sonnet 5 | high | 4.5% | $8.20 |
| Claude Sonnet 5 | xhigh | 7% | $9.95 |
| Claude Sonnet 5 | max | 10.3% | $11.6 |
| GPT-5.6 Sol | low | 7.9% | $1.46 |
| GPT-5.6 Sol | medium | 20.9% | $2.69 |
| GPT-5.6 Sol | high | 26.1% | $4.12 |
| GPT-5.6 Sol | xhigh | 28.5% | $5.39 |
| GPT-5.6 Sol | max | 37.3% | $7.89 |
- Exact values from the data published with Anthropic's announcement.
- OpenAI did not report GPT-6 Sol on this benchmark, so Anthropic shows GPT-5.6 Sol.
Accuracy against cost · reported by Anthropic on 28 Sept 2026 · exact values
Measures whether an agent's code changes would be merged.
- Claude Sonnet 5.5
- Claude Opus 5.5
- Claude Sonnet 5
- GPT-6 Sol
Show data table
| Model | Effort | Score | Cost per task |
|---|---|---|---|
| Claude Sonnet 5.5 | low | 29.3% | $0.19 |
| Claude Sonnet 5.5 | medium | 36.5% | $0.24 |
| Claude Sonnet 5.5 | high | 49.4% | $0.42 |
| Claude Sonnet 5.5 | xhigh | 52.1% | $1.59 |
| Claude Sonnet 5.5 | max | 46.2% | $20.8 |
| Claude Opus 5.5 | low | 47.3% | $0.40 |
| Claude Opus 5.5 | medium | 54.6% | $0.80 |
| Claude Opus 5.5 | high | 54% | $1.09 |
| Claude Opus 5.5 | xhigh | 51.4% | $2.25 |
| Claude Opus 5.5 | max | 54.4% | $6.19 |
| Claude Sonnet 5 | low | 28.7% | $2.39 |
| Claude Sonnet 5 | medium | 35.2% | $3.81 |
| Claude Sonnet 5 | high | 39.4% | $6.10 |
| Claude Sonnet 5 | xhigh | 42.7% | $10.1 |
| Claude Sonnet 5 | max | 42.4% | $17.1 |
| GPT-6 Sol | low | 37.3% | $0.43 |
| GPT-6 Sol | medium | 45.9% | $0.77 |
| GPT-6 Sol | high | 47.7% | $1.04 |
| GPT-6 Sol | xhigh | 48.4% | $1.32 |
| GPT-6 Sol | max | 49.3% | $2.07 |
- Exact values from the data published with Anthropic's announcement.
Accuracy against cost · reported by Anthropic on 28 Sept 2026 · exact values
Evaluates coding agents on ambiguous, multi-file tasks taken from real Cursor sessions.
- Claude Sonnet 5.5
- Claude Opus 5.5
- Claude Sonnet 5
- GPT-5.6 Sol
Show data table
| Model | Effort | Score | Cost per task |
|---|---|---|---|
| Claude Sonnet 5.5 | low | 35.8% | $0.50 |
| Claude Sonnet 5.5 | medium | 39.2% | $0.70 |
| Claude Sonnet 5.5 | high | 47.8% | $1.67 |
| Claude Sonnet 5.5 | xhigh | 53.1% | $3.88 |
| Claude Sonnet 5.5 | max | 55.5% | $9.67 |
| Claude Opus 5.5 | low | 43.7% | $1.17 |
| Claude Opus 5.5 | medium | 52.5% | $2.91 |
| Claude Opus 5.5 | high | 56% | $3.97 |
| Claude Opus 5.5 | xhigh | 56% | $6.98 |
| Claude Opus 5.5 | max | 57.8% | $13.4 |
| Claude Sonnet 5 | low | 24.1% | $1.39 |
| Claude Sonnet 5 | medium | 28% | $2.31 |
| Claude Sonnet 5 | high | 30.8% | $3.48 |
| Claude Sonnet 5 | xhigh | 32% | $4.55 |
| Claude Sonnet 5 | max | 34.1% | $7.17 |
| GPT-5.6 Sol | low | 24.6% | $0.87 |
| GPT-5.6 Sol | medium | 31.1% | $1.77 |
| GPT-5.6 Sol | high | 35.7% | $2.85 |
| GPT-5.6 Sol | xhigh | 37.7% | $4.40 |
| GPT-5.6 Sol | max | 41.7% | $8.23 |
- Exact values from the data published with Anthropic's announcement.
- CursorBench does not report GPT-6 Sol publicly, so Anthropic shows GPT-5.6 Sol.
Elo against cost · reported by Anthropic on 28 Sept 2026 · exact values
Artificial Analysis's benchmark of long-horizon knowledge work.
- Claude Sonnet 5.5
- Claude Opus 5.5
- Claude Sonnet 5
- GPT-6 Sol
Show data table
| Model | Effort | Elo | Cost per task |
|---|---|---|---|
| Claude Sonnet 5.5 | low | 1264 Elo | $0.87 |
| Claude Sonnet 5.5 | medium | 1461 Elo | $1.64 |
| Claude Sonnet 5.5 | high | 1634 Elo | $3.95 |
| Claude Sonnet 5.5 | xhigh | 1746 Elo | $9.63 |
| Claude Sonnet 5.5 | max | 1811 Elo | $29.2 |
| Claude Opus 5.5 | low | 1285 Elo | $1.15 |
| Claude Opus 5.5 | medium | 1642 Elo | $4.40 |
| Claude Opus 5.5 | high | 1705 Elo | $6.27 |
| Claude Opus 5.5 | xhigh | 1780 Elo | $12.3 |
| Claude Opus 5.5 | max | 1822 Elo | $21 |
| Claude Sonnet 5 | low | 923 Elo | $0.82 |
| Claude Sonnet 5 | medium | 1056 Elo | $1.73 |
| Claude Sonnet 5 | high | 1177 Elo | $3.76 |
| Claude Sonnet 5 | xhigh | 1274 Elo | $7.56 |
| Claude Sonnet 5 | max | 1359 Elo | $14.4 |
| GPT-6 Sol | low | 905 Elo | $0.12 |
| GPT-6 Sol | medium | 1142 Elo | $0.34 |
| GPT-6 Sol | high | 1289 Elo | $0.63 |
| GPT-6 Sol | xhigh | 1364 Elo | $1.19 |
| GPT-6 Sol | max | 1483 Elo | $2.67 |
- Exact values from the data published with Anthropic's announcement.
- Artificial Analysis ran Sonnet 5.5 on a pre-release deployment with a since-fixed structured output bug, which may slightly understate its score.
Anthropic: Introducing Claude Fable 5.1 and Claude Mythos 5.1Read announcement
Reported by Anthropic on 1 Sept 2026 · exact values
| Benchmark | Claude Fable 5.1 | Claude Fable 5 | Claude Opus 5 | GPT-5.6 Sol |
|---|---|---|---|---|
| Terminal-Bench-Science 0.1Agentic scientific research | 52.6% | 24.7% | 29% | 22.4% |
| Terminal-Bench 4.0Agentic coding | 55.8% | 42% | 52.3% | 37.3% |
| GDPval-AA v2Knowledge work | 1853 Elo | 1723 Elo | 1824 Elo | 1711 Elo |
| OSWorld 2.0Computer use · partial | 77.9% | 72.9% | 75.4% | – |
| OSWorld 2.0 (strict)Computer use · strict | 41.7% | 36.1% | 39.6% | – |
| Humanity's Last Exam (no tools)Multidisciplinary reasoning · no tools | 60.9% | 57.8% | 56.6% | – |
| Humanity's Last Exam (with tools)Multidisciplinary reasoning · with tools | 65% | 63.8% | 63.6% | – |
| AutomationBenchBusiness workflows | 31.4% | 17.1% | 26.9% | 19.6% |
| CursorBench 3.2.0Agentic coding | 73.4% | 70.5% | 70% | 67.2% |
- Bold marks the best reported score in each row.
- Fable 5.1 was evaluated with production safeguards enabled. Where they intervened, Fable 5.1 and Fable 5 scored zero on OSWorld 2.0 and Fable 5 scored zero on AutomationBench.
- Claude Mythos 5.1, the same underlying model with access limited to vetted users, scores 60.9% on Terminal-Bench 4.0. Mythos has no public API price, so it is not tracked here.
- A dash means the lab did not report a result for that model.
Accuracy against cost · reported by Anthropic on 1 Sept 2026 · exact values
Terminal-based agentic scientific research tasks, in Anthropic's agentic scientific research category.
- Claude Fable 5.1
- Claude Fable 5
Show data table
| Model | Effort | Score | Cost per task |
|---|---|---|---|
| Claude Fable 5.1 | low | 26.3% | $11.1 |
| Claude Fable 5.1 | medium | 35.7% | $14.9 |
| Claude Fable 5.1 | high | 40% | $20.3 |
| Claude Fable 5.1 | xhigh | 49.5% | $31.8 |
| Claude Fable 5.1 | max | 52.6% | $37.9 |
| Claude Fable 5 | low | 12.3% | $17.1 |
| Claude Fable 5 | medium | 21.4% | $25 |
| Claude Fable 5 | high | 25% | $34.3 |
| Claude Fable 5 | xhigh | 23.4% | $36 |
| Claude Fable 5 | max | 24.7% | $44.1 |
- Exact values from the data published with Anthropic's announcement.
- Standard error is about 3.5 to 4.5 points per model.
Pass rate against cost · reported by Anthropic on 1 Sept 2026 · exact values
Expert-level questions across many disciplines, answered with access to tools.
- Claude Fable 5.1
- Claude Fable 5
Show data table
| Model | Effort | Pass rate | Cost per task |
|---|---|---|---|
| Claude Fable 5.1 | low | 60% | $0.52 |
| Claude Fable 5.1 | medium | 62.96% | $0.67 |
| Claude Fable 5.1 | high | 64.76% | $1.05 |
| Claude Fable 5.1 | xhigh | 65.08% | $2.28 |
| Claude Fable 5.1 | max | 65% | $3.20 |
| Claude Fable 5 | low | 59.64% | $0.61 |
| Claude Fable 5 | medium | 61.4% | $1.01 |
| Claude Fable 5 | high | 63.16% | $1.42 |
| Claude Fable 5 | xhigh | 63.52% | $1.92 |
| Claude Fable 5 | max | 63.8% | $3.44 |
- Exact values from the data published with Anthropic's announcement.
Pass rate against cost · reported by Anthropic on 1 Sept 2026 · exact values
Expert-level questions across many disciplines, answered without tools.
- Claude Fable 5.1
- Claude Fable 5
Show data table
| Model | Effort | Pass rate | Cost per task |
|---|---|---|---|
| Claude Fable 5.1 | low | 53.16% | $0.30 |
| Claude Fable 5.1 | medium | 55.92% | $0.46 |
| Claude Fable 5.1 | high | 57.96% | $0.75 |
| Claude Fable 5.1 | xhigh | 60.36% | $1.53 |
| Claude Fable 5.1 | max | 60.92% | $2.23 |
| Claude Fable 5 | low | 50.6% | $0.17 |
| Claude Fable 5 | medium | 55.88% | $0.40 |
| Claude Fable 5 | high | 56.88% | $0.62 |
| Claude Fable 5 | xhigh | 57.44% | $0.91 |
| Claude Fable 5 | max | 57.76% | $1.70 |
- Exact values from the data published with Anthropic's announcement.
Accuracy against cost · reported by Anthropic on 1 Sept 2026 · exact values
Evaluates coding agents on tasks taken from real Cursor sessions (earlier release than CursorBench 4.0).
- Claude Fable 5.1
- Claude Fable 5
Show data table
| Model | Effort | Score | Cost per task |
|---|---|---|---|
| Claude Fable 5.1 | low | 66.2% | $2.90 |
| Claude Fable 5.1 | medium | 68% | $3.53 |
| Claude Fable 5.1 | high | 69.4% | $4.80 |
| Claude Fable 5.1 | xhigh | 72.8% | $6.96 |
| Claude Fable 5.1 | max | 73.4% | $9.64 |
| Claude Fable 5 | low | 62.1% | $4.46 |
| Claude Fable 5 | medium | 65.2% | $6.80 |
| Claude Fable 5 | high | 66.5% | $8.77 |
| Claude Fable 5 | xhigh | 68.4% | $11.7 |
| Claude Fable 5 | max | 70.5% | $17.3 |
- Exact values from the data published with Anthropic's announcement.
Google DeepMind: Gemini 4 Argon performance and methodologyRead announcement
Reported by Google DeepMind on 30 Sept 2026 · exact values
Exact published scores · Higher is better. Unreported results are omitted.
| Benchmark | Gemini 4 Argon | GPT-6 Astra | Claude Fable 5.1 | Claude Opus 5.5 |
|---|---|---|---|---|
| Vals IndexKnowledge work | 68.9% | 63.1% | 65.8% | 67% |
| AutomationBenchKnowledge work · Score | 51.3% | 41.4% | 31.4% | 42.5% |
| Vals Finance Agent v2Knowledge work | 65.4% | 53.5% | 58.9% | 58.6% |
| Harvey's Legal Agent BenchmarkKnowledge work | 19.6% | 5.4% | 6.7% | 3.8% |
| DeepSWE v1.1Agentic coding | 77.9% | 74.1% | 67.4% | 74.2% |
| FrontierSWE v2Agentic coding | 55% | 65.5% | 56.3% | 62.3% |
| Vibe Code BenchAgentic coding | 91.9% | 89.6% | 90.3% | 90.3% |
| Terminal-bench 4.0Agentic coding | 57.4% | 58.2% | 57.9% | 66.4% |
| PostTrainBenchML engineering | 45.3% | 44.3% | 40.2% | 49.3% |
| Terminal-Bench Science 0.1Science and math | 57.6% | 68.1% | 52.6% | 63.3% |
| LABBench 2Science and math | 88.8% | 85.4% | 68.6% | 73.1% |
| RiemannBenchScience and math | 76% | 72% | 65.6% | 69.6% |
| GraphWalksLong context · Up to 128k, BFS (F1) | 99.7% | 98.7% | 91.4% | 90.6% |
| GraphWalksLong context · 256k to 1M, BFS (F1) | 84.2% | 71.8% | 65% | 66.8% |
| Agent's Last ExamComputer use · Pass rate | 39.5% | 34.2% | – | 38.2% |
| OSWorld-2.0Computer use · Offline subset Partial score | 69.2% | 72.6% | – | – |
| ChartographyMultimodal understanding | 71.6% | 71% | 46.2% | 66.3% |
| LVBenchMultimodal understanding | 91.7% | 87.5% | 79.7% | 83.7% |
| CWE-bench v1Cybersecurity | 68% | 68% | 58% | 67% |
View Google DeepMind's original charts
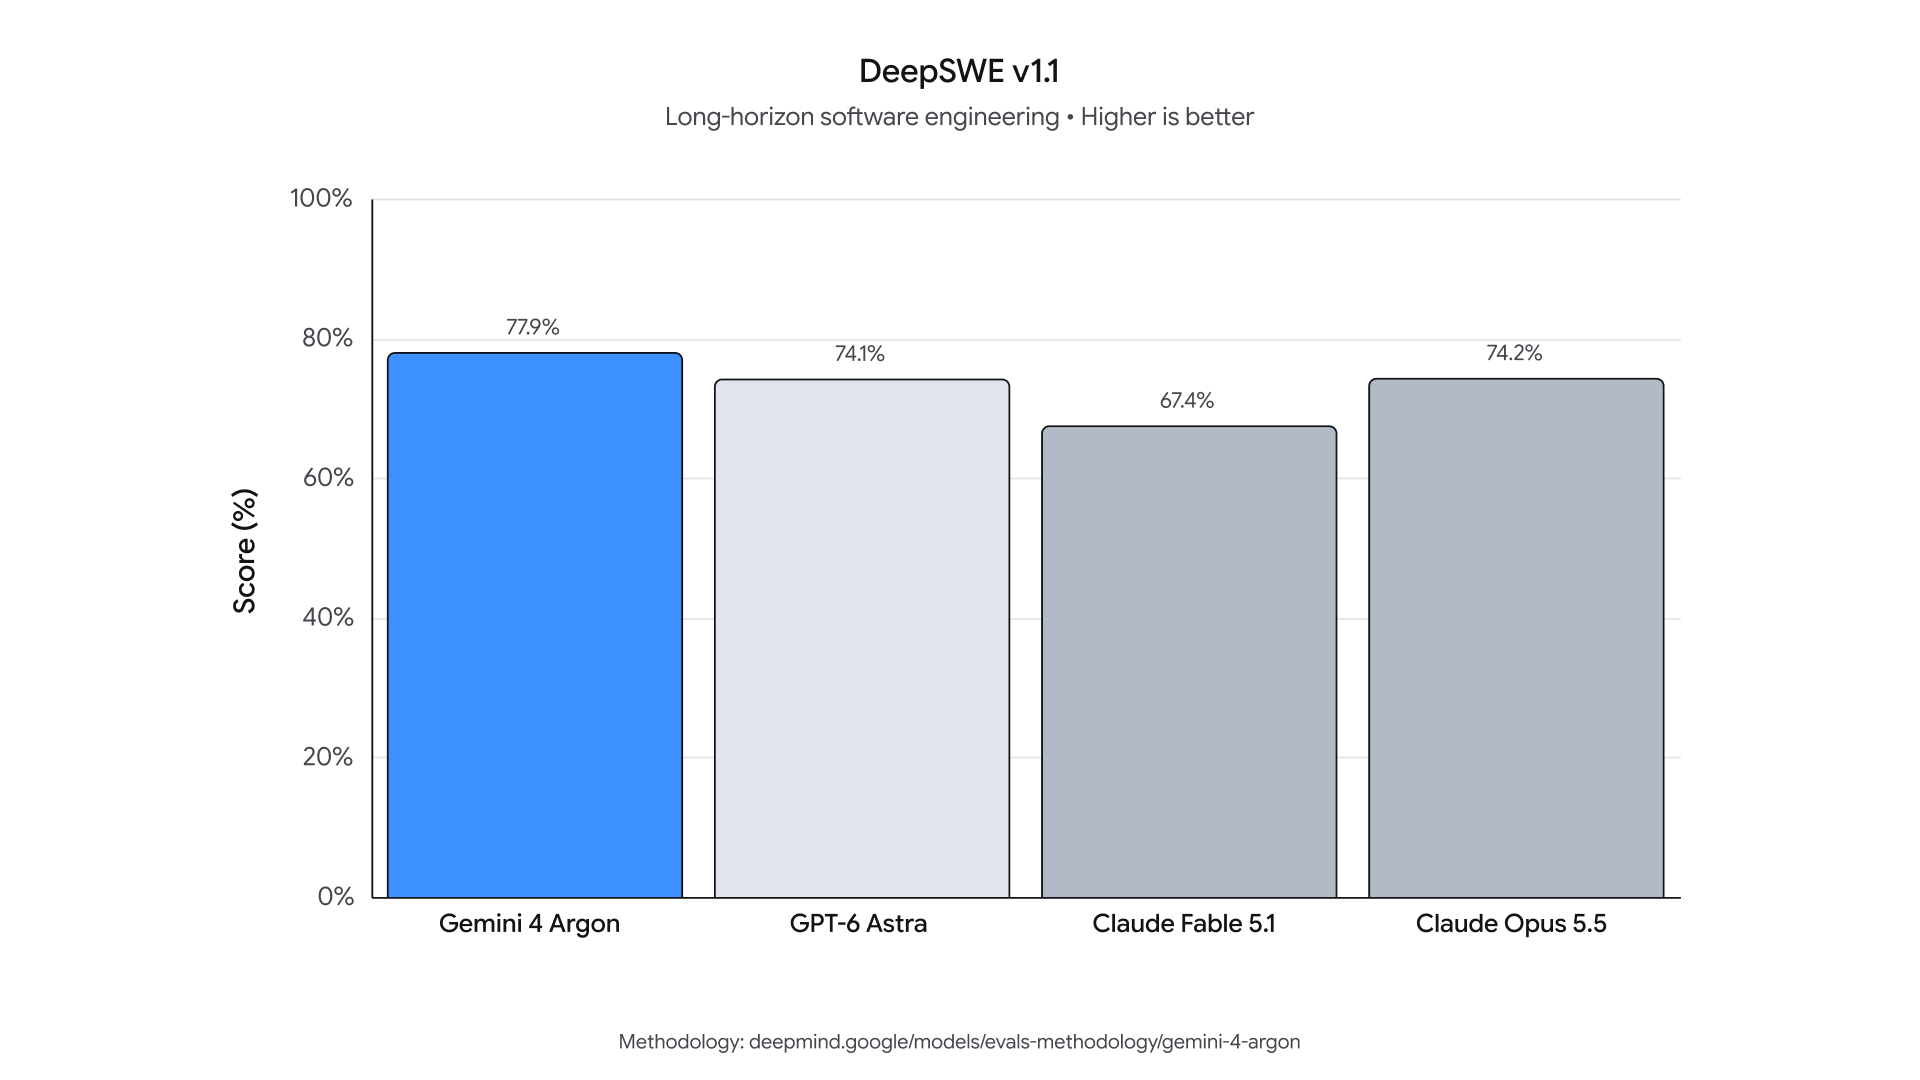
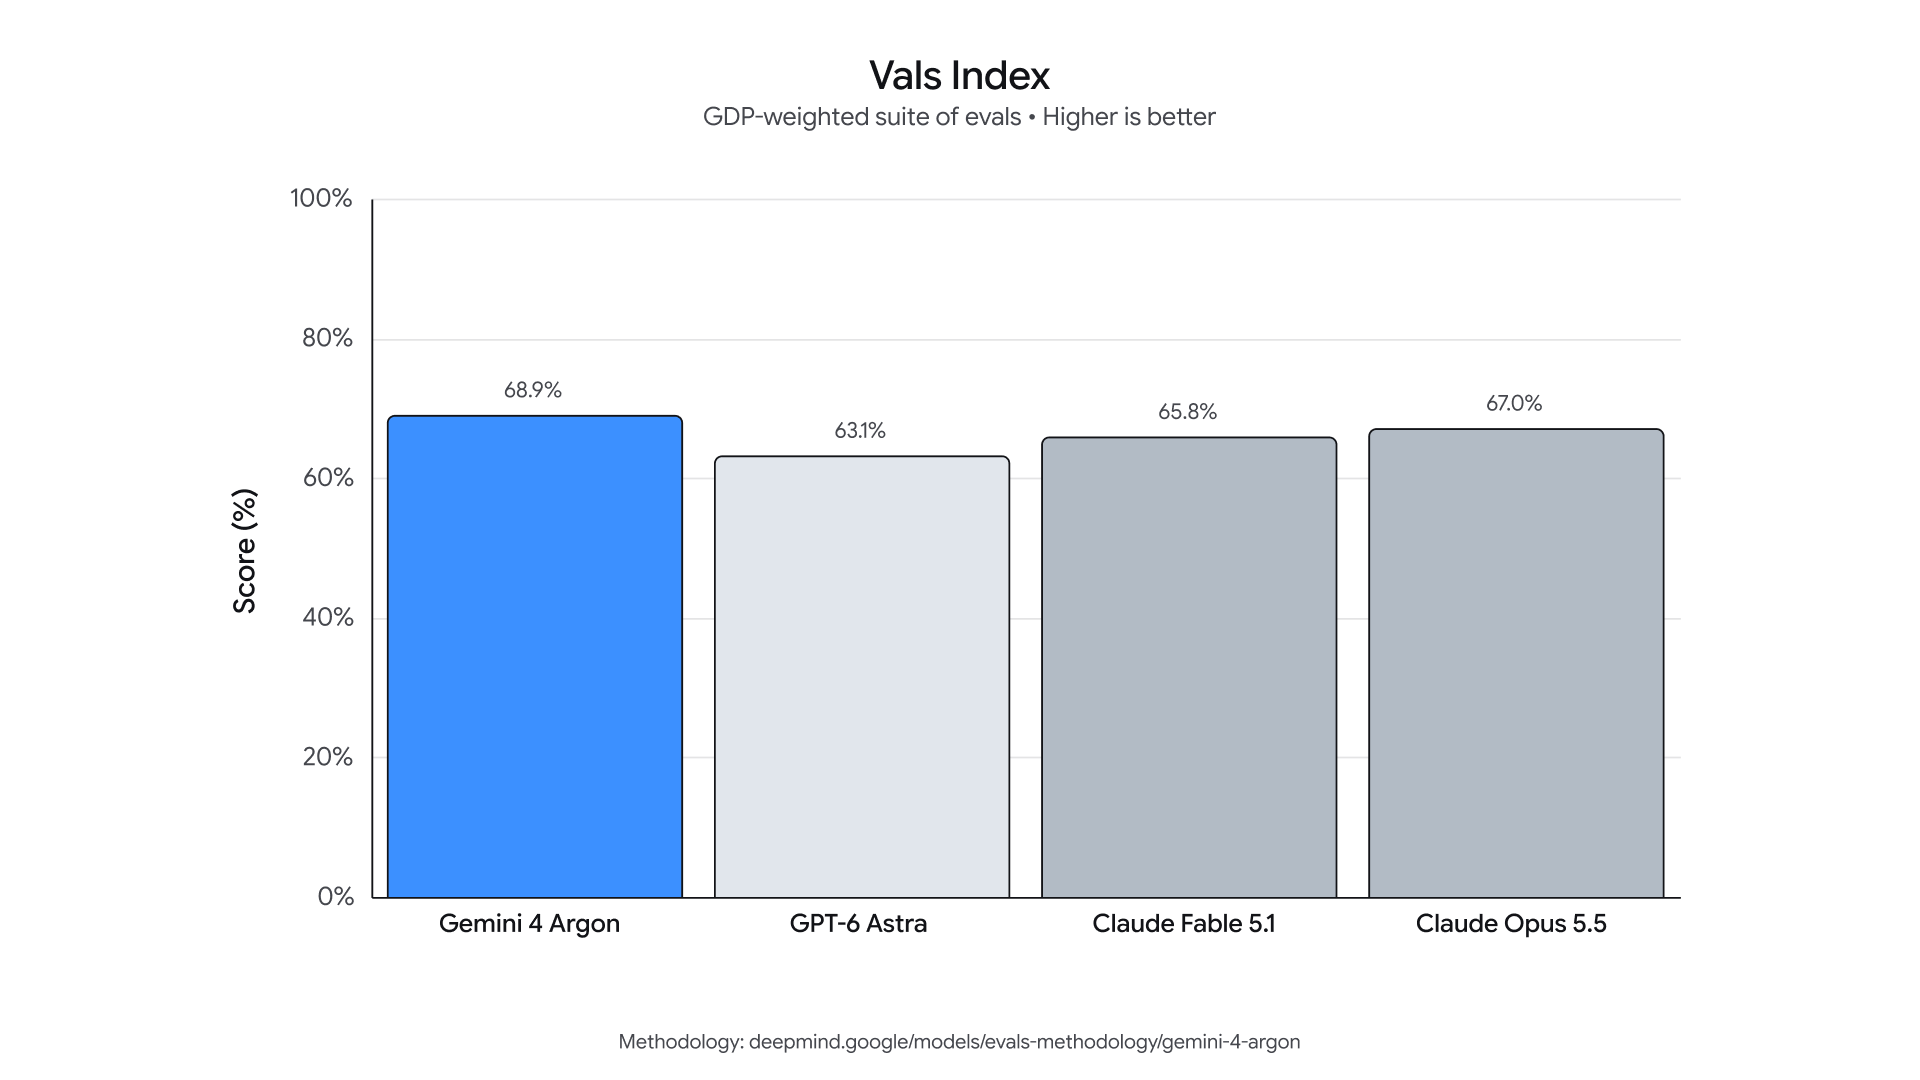
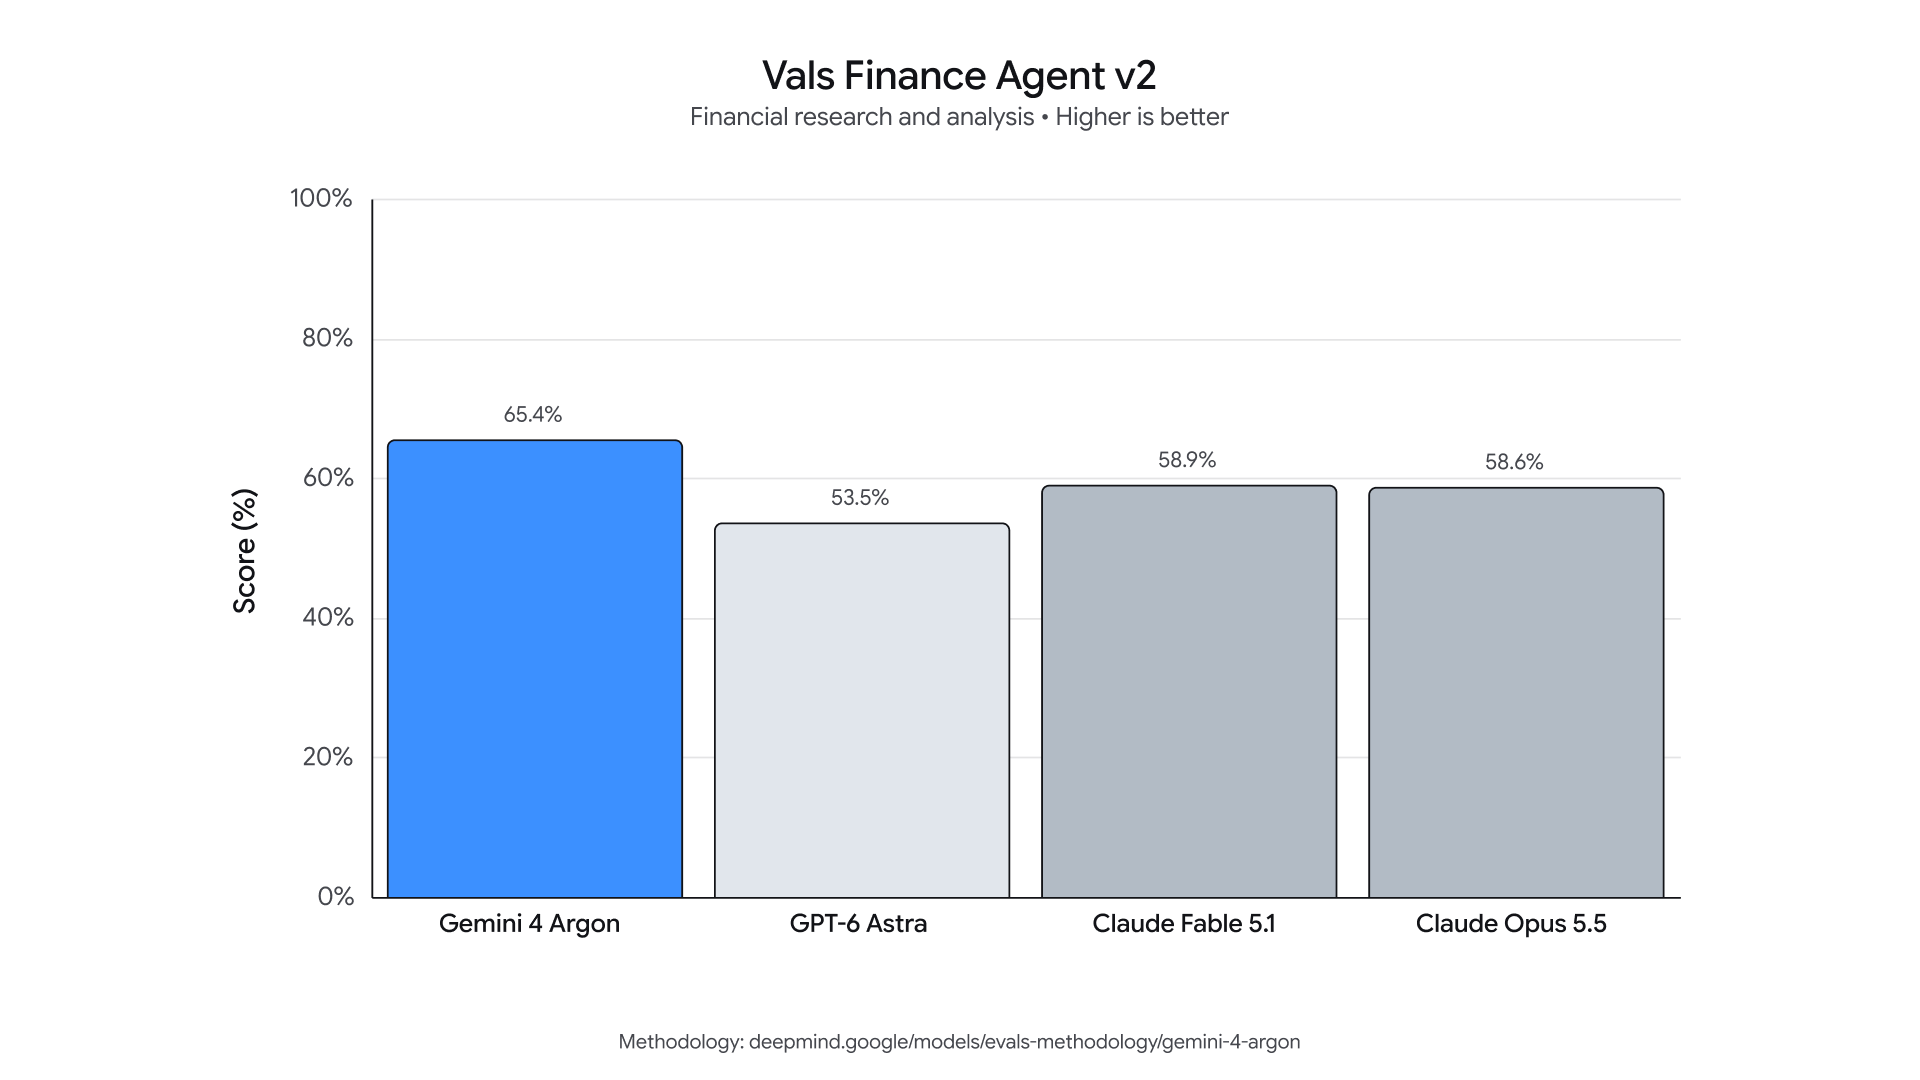
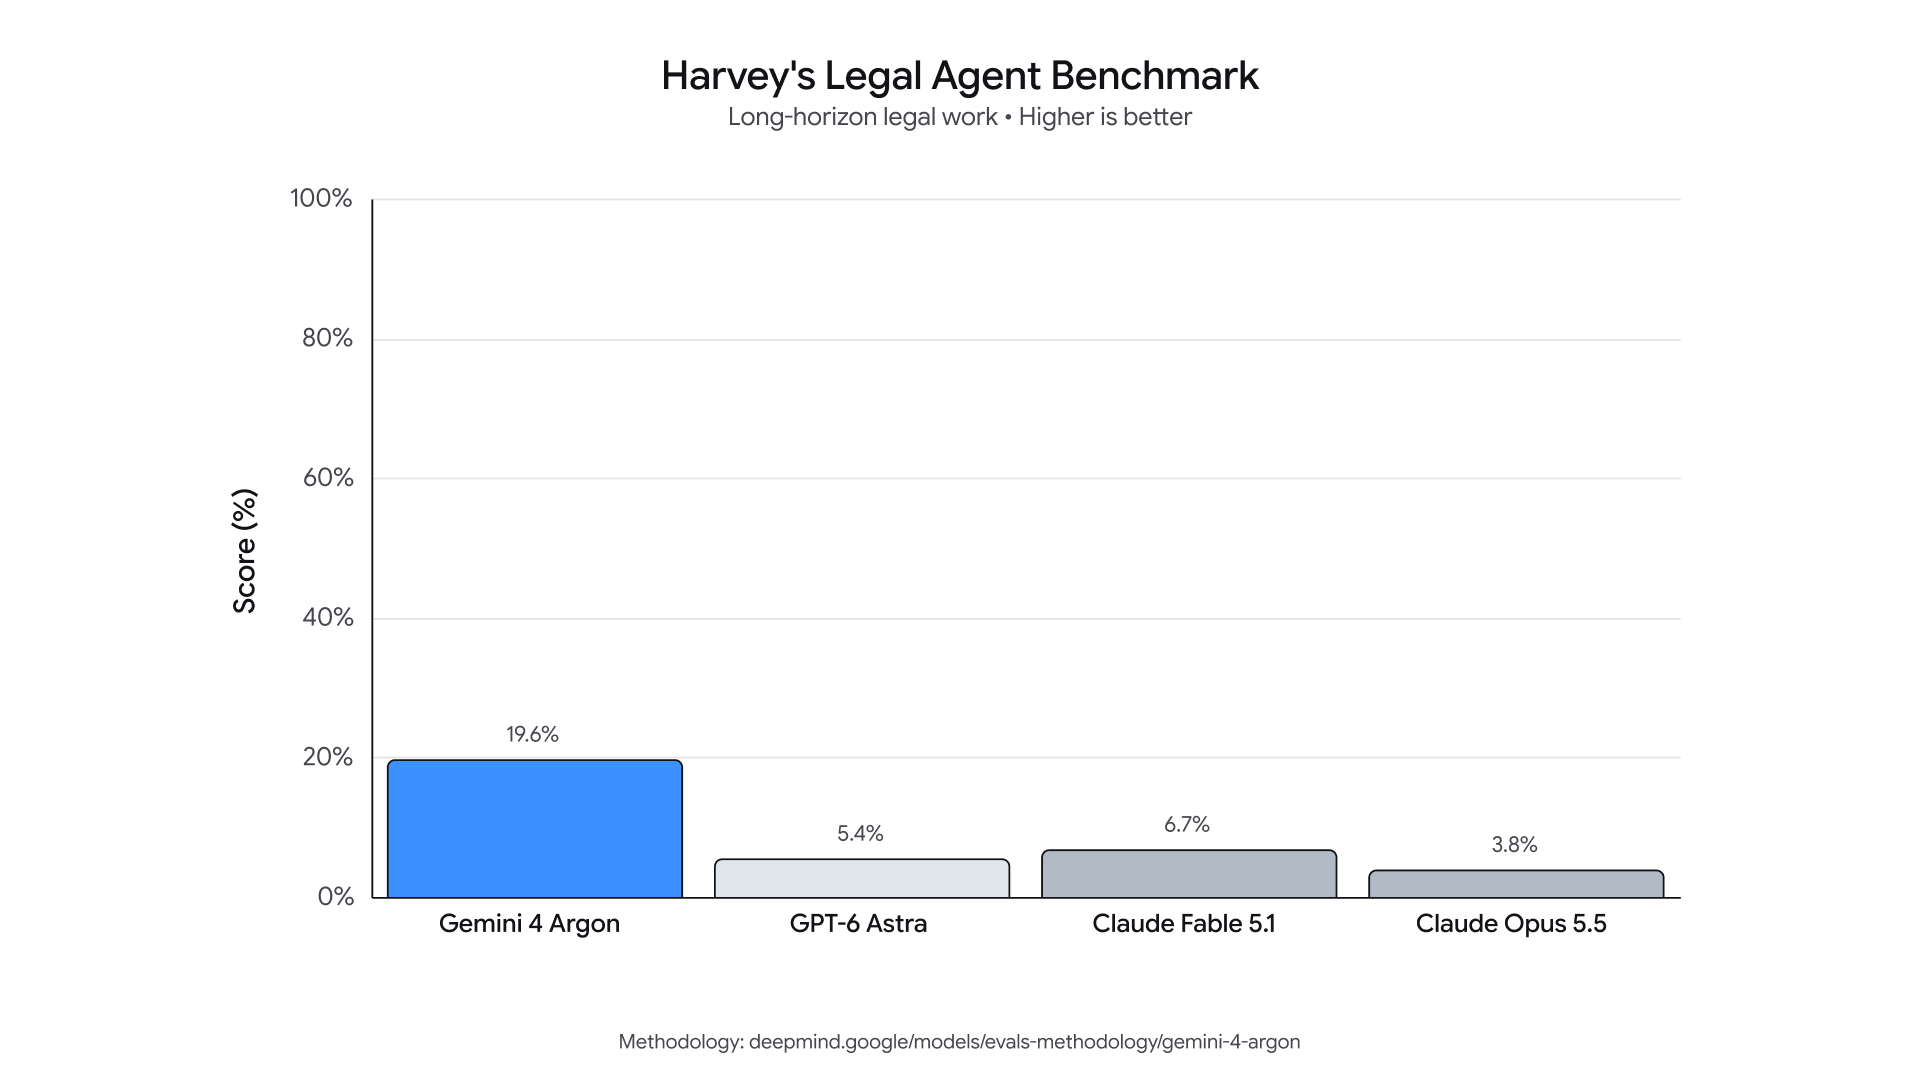
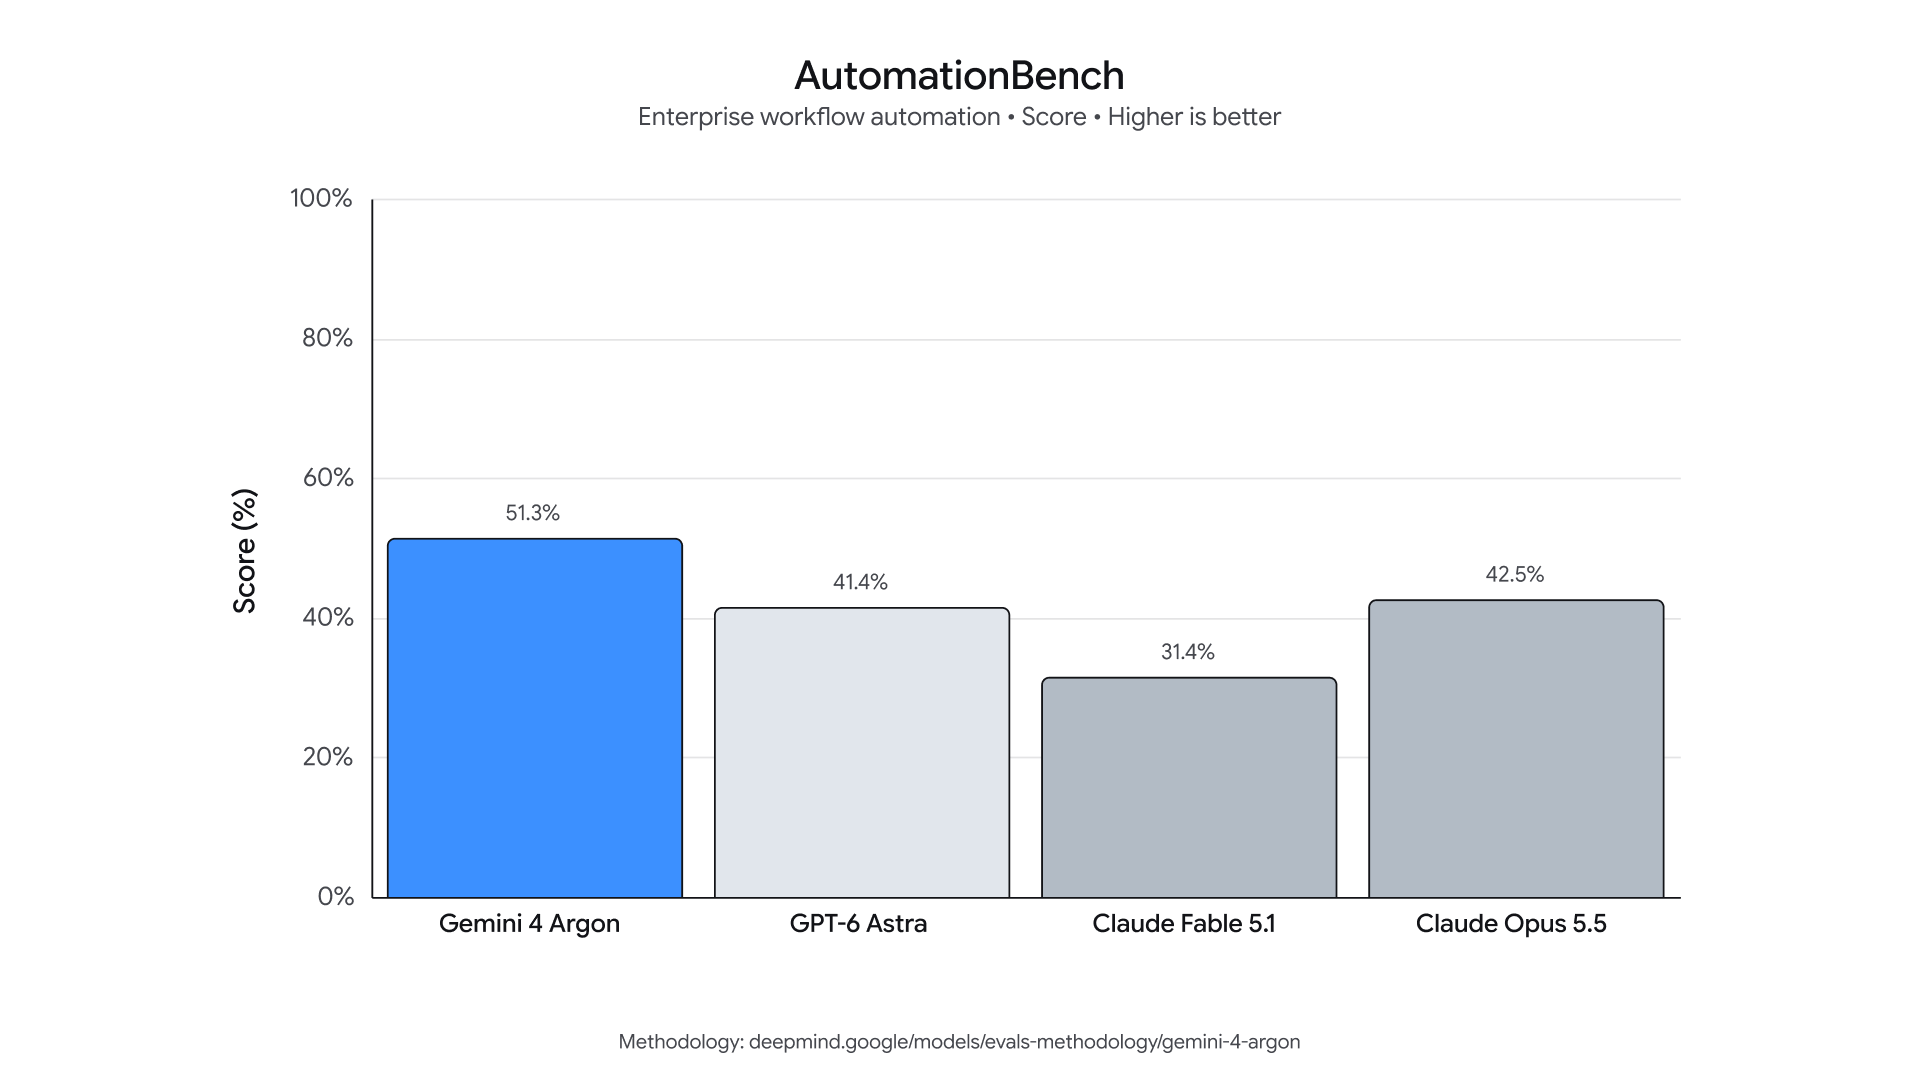
- Bold marks the best reported score in each row.
- Exact scores from Google DeepMind's performance table. Argon is initially available to trusted testers.
- OSWorld-2.0 uses the offline subset and partial scoring. GraphWalks reports BFS F1, with separate context ranges.
- Scores reflect Google's published evaluation setup. Benchmark versions and harnesses can differ from other labs' launch results. A dash means no result was published.
Google DeepMind: Gemini 3.8 Flash model cardRead announcement
Reported by Google DeepMind on 2 Sept 2026 · exact values
Exact published scores · Higher is better. Unreported results are omitted.
| Benchmark | Gemini 3.8 Flash | Gemini 3.7 Flash | Claude Opus 5 | Claude Sonnet 5 | GPT-5.6 Sol | GPT-5.6 Terra |
|---|---|---|---|---|---|---|
| DeepSWE v1.1Long-horizon software engineering | 73.7% | 65.3% | 74% | 53.8% | 72.7% | 69.6% |
| GDPVal-AA v2Knowledge work · Elo | 1545 Elo | 1482 Elo | 1824 Elo | 1584 Elo | 1710 Elo | 1528 Elo |
| Vals Finance Agent v2Financial analyst tasks | 61.4% | 59% | 58.6% | 53.9% | 53.8% | 54.4% |
| Harvey's Legal Agent BenchmarkComplex legal workflows · All pass rate | 10% | 8.8% | 6.7% | 5% | 2.5% | 0.8% |
| Terminal-bench 2.1Agentic terminal coding | 89.4% | 85.8% | 89.1% | 80.4% | 88.8% | 87.4% |
| Terminal-bench 4.0General agent capabilities | 19.1% | 11.2% | 51.8% | 12.4% | 37.3% | 23.6% |
| GDP.PDFExpert PDF document comprehension · All pass rate | 35% | 34% | 37% | 28% | 40% | 29% |
| CharXiv ReasoningInformation synthesis from complex charts · No tools | 86.2% | 84.5% | 83.7% | 70.1% | 85.8% | 85.9% |
| LVBenchLong video understanding · (agentic) | 87.8% | 85.4% | 75.4% | 68.5% | 82.1% | 78.9% |
| LVBenchLong video understanding · (static) | 87.1% | – | – | – | – | – |
| HLE-VerifiedMultidisciplinary expert reasoning | 54.9% | 53.6% | 54.4% | 31% | 54.5% | 51.1% |
| OSWorld-2.0Agentic computer use · Partial score batch tool enabled | 59% | 50.6% | 75.4% | 42.6% | 62.6% | 50.2% |
| BioMysteryBenchBioinformatics research workflows · Human Solvable | 88.8% | 87.1% | 90.1% | 87.5% | 79.5% | 83.8% |
| BioMysteryBenchBioinformatics research workflows · Human Difficult | 56.5% | 43.5% | 49.4% | 34.1% | 44.7% | 49.4% |
| LABBench2Biology real-world research tasks | 86.2% | 82.1% | 84.2% | 80.1% | 82.1% | 81.2% |
View Google DeepMind's original charts
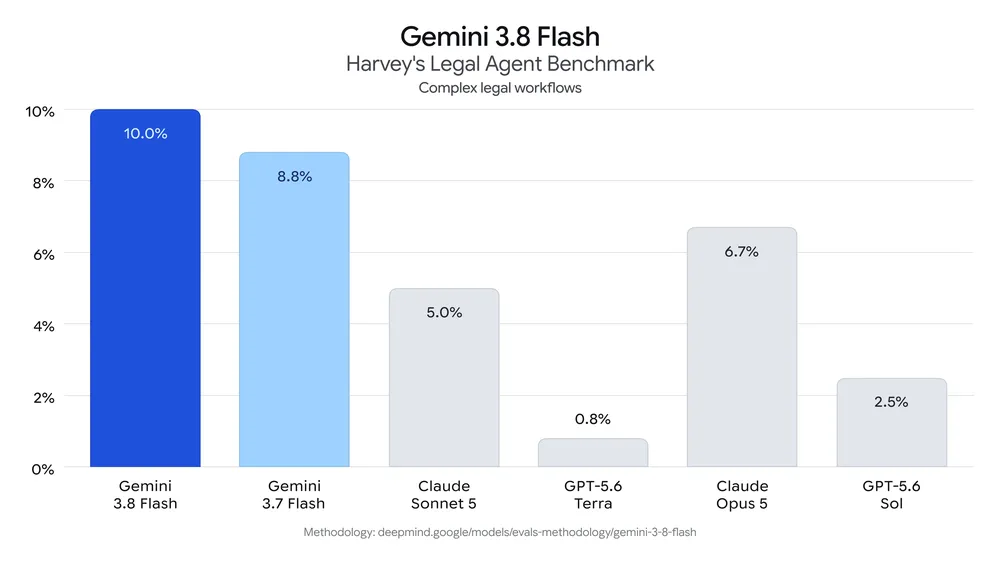
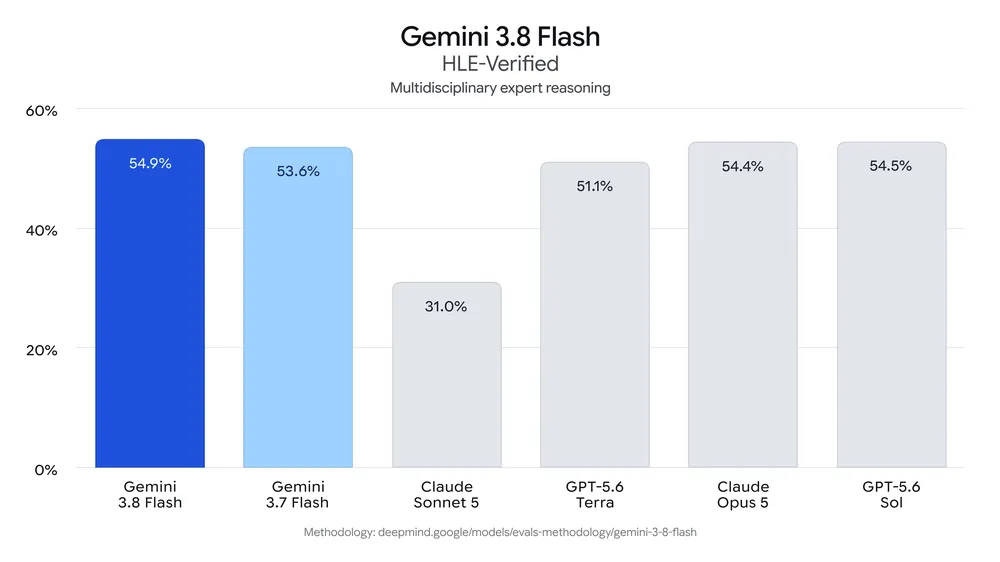
- Bold marks the best reported score in each row.
- Exact scores from the Google DeepMind model card. Gemini 3.7 Flash and GPT-5.6 Terra are benchmark comparisons only.
- LVBench reports separate agentic and static results for Gemini 3.8 Flash. Competitor cells span both rows in the source; they appear alongside the agentic result here, with no separate static values inferred. OSWorld-2.0 uses partial scoring with the batch tool enabled.
- These are Google-reported results; keep benchmark versions and evaluation harnesses in mind when comparing other launch tables.
Google DeepMind: Gemini 3.5 Flash-Lite model cardRead announcement
Reported by Google DeepMind on 21 Jul 2026 · exact values
Exact published scores · Higher is better. Unreported results are omitted.
| Benchmark | Gemini 3.5 Flash-Lite | Gemini 3.1 Flash-Lite | GPT-5.4 mini | Claude Haiku 4.5 |
|---|---|---|---|---|
| SWE-Bench Pro (Public)Diverse agentic coding tasks | 54.2% | 38.3% | 54.4% | 39.5% |
| Terminal-bench 2.1Agentic terminal coding · Terminus-2 harness | 54% | 31% | 59.2% | 44.2% |
| MLE-BenchMachine Learning Engineering | 39.2% | 22% | – | – |
| GDPVal-AA v2Knowledge work · Elo | 1140 Elo | 642 Elo | 1171 Elo | 907 Elo |
| OSWorld-VerifiedAgentic computer use | 74% | 54.3% | 72.1% | 50.7% |
| CharXiv ReasoningInformation synthesis from complex charts · No tools | 74.5% | 73.2% | 80.3% | 61.7% |
| CharXiv ReasoningInformation synthesis from complex charts · With tools | 76.5% | 75.6% | – | – |
| GDM-MRCR v2 (8-needle)Long context performance · 128k (average) | 72.2% | 60.1% | 42.7% | 35.3% |
| GDM-MRCR v2 (8-needle)Long context performance · 1M (pointwise) | 21.3% | 12.3% | – | – |
- Bold marks the best reported score in each row.
- Exact scores from the Google DeepMind model card. Earlier competitor models are preserved as benchmark comparisons only.
- CharXiv reports results with and without tools. Long-context results use separate 128K average and 1M pointwise settings. A dash means no result was published.
Google DeepMind: Gemini 3.1 Pro model cardRead announcement
Reported by Google DeepMind on 19 Feb 2026 · exact values
Exact published scores · Higher is better. Unreported results are omitted.
| Benchmark | Gemini 3.1 Pro (high) | Gemini 3 Pro (high) | Claude Sonnet 4.6 (max) | Claude Opus 4.6 (max) | GPT-5.2 (xhigh) | GPT-5.3-Codex (xhigh) |
|---|---|---|---|---|---|---|
| Humanity's Last ExamAcademic reasoning (full set, text + MM) · No tools | 44.4% | 37.5% | 33.2% | 40% | 34.5% | – |
| Humanity's Last ExamAcademic reasoning (full set, text + MM) · Search (blocklist) + Code | 51.4% | 45.8% | 49% | 53.1% | 45.5% | – |
| ARC-AGI-2Abstract reasoning puzzles · ARC Prize Verified | 77.1% | 31.1% | 58.3% | 68.8% | 52.9% | – |
| GPQA DiamondScientific knowledge · No tools | 94.3% | 91.9% | 89.9% | 91.3% | 92.4% | – |
| Terminal-Bench 2.0Agentic terminal coding · Terminus-2 harness | 68.5% | 56.9% | 59.1% | 65.4% | 54% | 64.7% |
| Terminal-Bench 2.0Agentic terminal coding · Other best self-reported harness · (Codex) | – | – | – | – | 62.2% | 77.3% |
| SWE-Bench VerifiedAgentic coding · Single attempt | 80.6% | 76.2% | 79.6% | 80.8% | 80% | – |
| SWE-Bench Pro (Public)Diverse agentic coding tasks · Single attempt | 54.2% | 43.3% | – | – | 55.6% | 56.8% |
| LiveCodeBench ProCompetitive coding problems from Codeforces, ICPC, and IOI · Elo | 2887 Elo | 2439 Elo | – | – | 2393 Elo | – |
| SciCodeScientific research coding | 59% | 56% | 47% | 52% | 52% | – |
| APEX-AgentsLong horizon professional tasks | 33.5% | 18.4% | – | 29.8% | 23% | – |
| GDPval-AA EloExpert tasks | 1317 Elo | 1195 Elo | 1633 Elo | 1606 Elo | 1462 Elo | – |
| τ2-benchAgentic and tool use · Retail | 90.8% | 85.3% | 91.7% | 91.9% | 82% | – |
| τ2-benchAgentic and tool use · Telecom | 99.3% | 98% | 97.9% | 99.3% | 98.7% | – |
| MCP AtlasMulti-step workflows using MCP | 69.2% | 54.1% | 61.3% | 59.5% | 60.6% | – |
| BrowseCompAgentic search · Search + Python + Browse | 85.9% | 59.2% | 74.7% | 84% | 65.8% | – |
| MMMU-ProMultimodal understanding and reasoning · No tools | 80.5% | 81% | 74.5% | 73.9% | 79.5% | – |
| MMMLUMultilingual Q&A | 92.6% | 91.8% | 89.3% | 91.1% | 89.6% | – |
| MRCR v2 (8-needle)Long context performance · 128k (average) | 84.9% | 77% | 84.9% | 84% | 83.8% | – |
| MRCR v2 (8-needle)Long context performance · 1M (pointwise) | 26.3% | 26.3% | – | – | – | – |
View Google DeepMind's original charts
- Bold marks the best reported score in each row.
- Exact scores from the Google DeepMind model card. Gemini models use high thinking, Claude models use max thinking and GPT models use xhigh thinking.
- Terminal-Bench results using the Terminus-2 harness and the best self-reported Codex harness are separate rows. Do not combine them as one evaluation.
- Historical competitors are benchmark comparisons only. A dash means no published result or unsupported context length.